Running BigQuery, Spark, and Trino on One Iceberg Table
One Iceberg table on Cloud Storage serves BigQuery, Spark, and Trino without copies. Here's how to set it up with the Lakehouse runtime catalog.
In Partnership with Google Cloud
Here is a common data engineering setup: BigQuery for analytics, Apache Spark for pipelines, and Trino for ad hoc questions that land on a Friday afternoon. Each engine gets its own copy of the data, while sync jobs do their best to keep this data aligned.
Despite best efforts, data doesn’t always stay consistent, and the lag between syncs inevitably becomes an issue. Consider a scenario where BigQuery says that an order status is shipped, while the Spark copy reports paid and awaiting shipment. No one can trust either until the next sync job finishes. Even if it eventually does finish, you’re still paying for compute time to perform the sync and storage for multiple copies. And if it doesn’t finish? You pay for engineering time to trace and fix the pipeline issues.
Google Cloud’s borderless Lakehouse and the Apache Iceberg open table format work together to help solve this. Every engine can read the same Parquet files and the same metadata layout without having to create separate copies. A shared catalog and commit protocol ensure that the engines agree on where the current version of the table lives, and on how a change gets committed without one writer trampling another.
To test it out, I built a project of my own: one orders table, one Cloud Storage bucket registered once in the Lakehouse runtime catalog. Apache Spark creates and loads the table, Trino appends to it, and BigQuery updates and merges rows in place. Then I made Spark and Trino write at the same moment, on purpose, to see what Iceberg does when two commits collide.
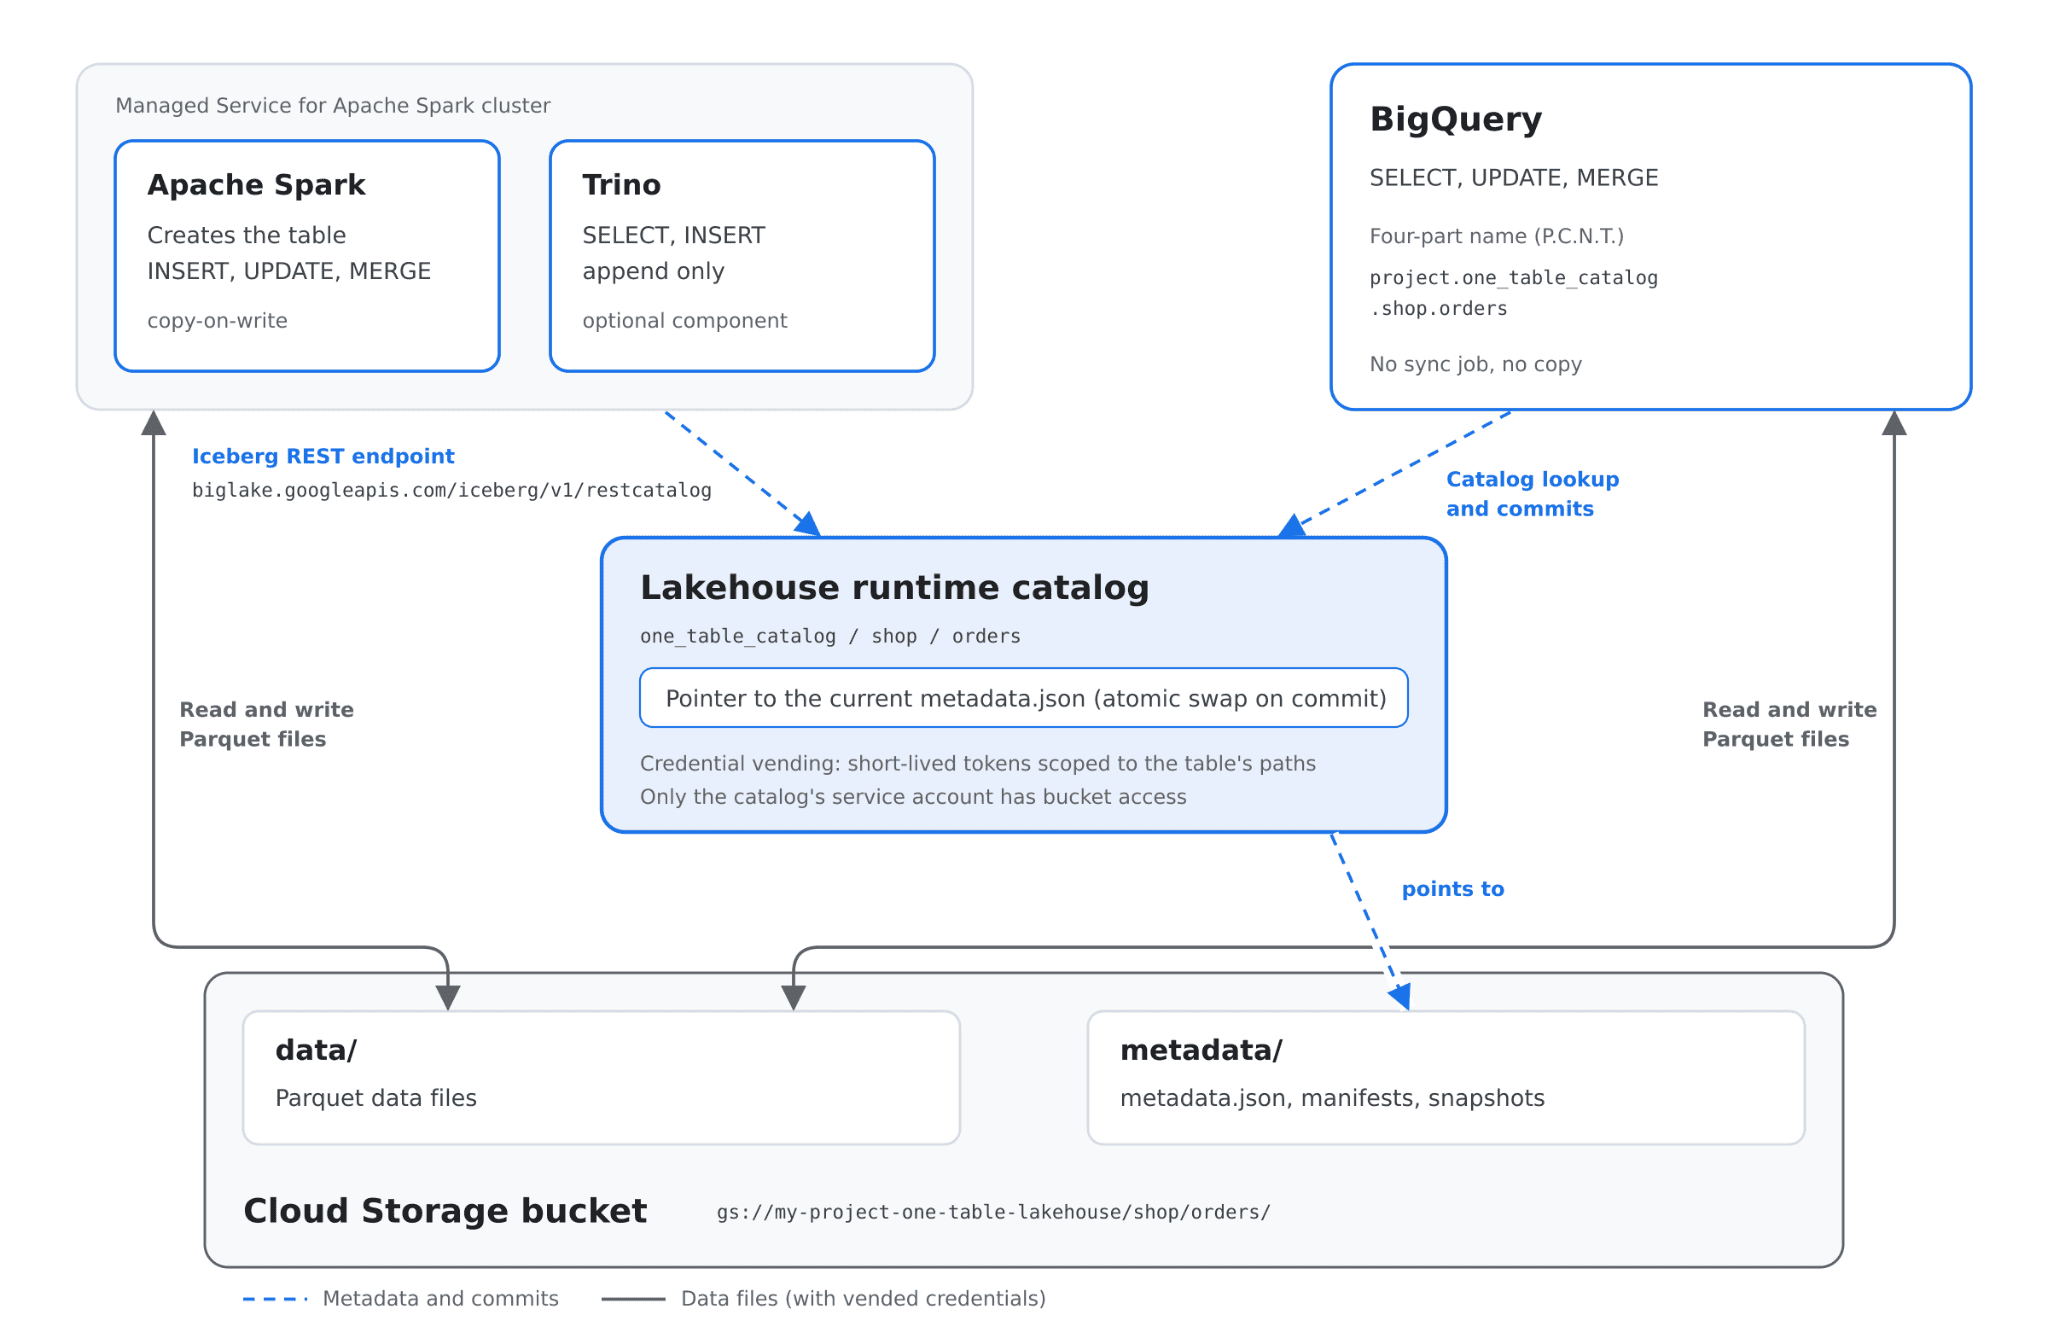
Figure 1. The project architecture.
I ran every command here in a fresh Google Cloud project, and I’ve reported the outputs as they came back. You can find the full set of scripts in this repository.
Architecture Overview: One Bucket, One Catalog, Three Engines
The mental model is small. Every data file and every metadata file for the table sits in one Cloud Storage location. The catalog doesn’t hold any data. Instead, it holds one thing of great importance: a pointer to each table’s current version via its metadata.json file. Change the pointer, and you’ve changed the table.
Spark and Trino reach the Lakehouse runtime catalog through the standard Apache Iceberg REST catalog endpoint (https://biglake.googleapis.com/iceberg/v1/restcatalog).
BigQuery doesn’t need any connector setup. It reads the same table with a four-part name:
project.catalog.namespace.tableFor this guide, the four-part name is:
my-project.one_table_catalog.shop.ordersThis is referred to as the P.C.N.T. naming convention, for Project.Catalog.Namespace.Table, which parallels BigQuery dataset syntax.
The last design choice is who can access the bucket. The catalog supports two credential modes:
| Mode | Who needs bucket access | What the engine gets |
|---|---|---|
| End-user credentials | Every user and every job service account | Nothing extra; each caller uses its own identity against Cloud Storage |
| Credential vending mode | Only the catalog’s own service account | A short-lived token scoped to the paths of the table being read or written |
I went with credential vending mode. With three engines and their service accounts in play, I’d rather grant bucket access to exactly one identity and manage everything else through catalog roles.
Step 1: Creating the Catalog and the Bucket
The bucket comes first. After that, the catalog is a single gcloud command.
export PROJECT_ID="my-project"
export REGION="us-central1"
export BUCKET_NAME="${PROJECT_ID}-one-table-lakehouse"
export CATALOG_ID="one_table_catalog"

gcloud storage buckets create gs://${BUCKET_NAME} \
  --project=${PROJECT_ID} \
  --location=${REGION} \
  --uniform-bucket-level-access

gcloud biglake iceberg catalogs create ${CATALOG_ID} \
  --project=${PROJECT_ID} \
  --catalog-type=biglake \
  --default-location=gs://${BUCKET_NAME} \
  --credential-mode=vended-credentials
The flag to watch is --catalog-type=biglake. That gives you a multiple-bucket catalog, whose name doesn’t have to match a bucket and which can grow to more storage paths later.
The catalog gets its own service account. With credential vending mode, it’s the only identity that needs to touch the bucket:
CATALOG_SA=$(gcloud biglake iceberg catalogs describe ${CATALOG_ID} \
  --project=${PROJECT_ID} \
  --format='value(biglake-service-account)')

gcloud storage buckets add-iam-policy-binding gs://${BUCKET_NAME} \
  --member="serviceAccount:${CATALOG_SA}" \
  --role="roles/storage.objectUser"
That service account is created asynchronously, so the grant can fail if you run it immediately after its creation. If so, wait 20 seconds and run it again. The repo’s script retries on its own.
The describe output for my project came back with credential-mode: CREDENTIAL_MODE_VENDED_CREDENTIALS and catalog-type: CATALOG_TYPE_BIGLAKE. In your project, you can check both to verify.
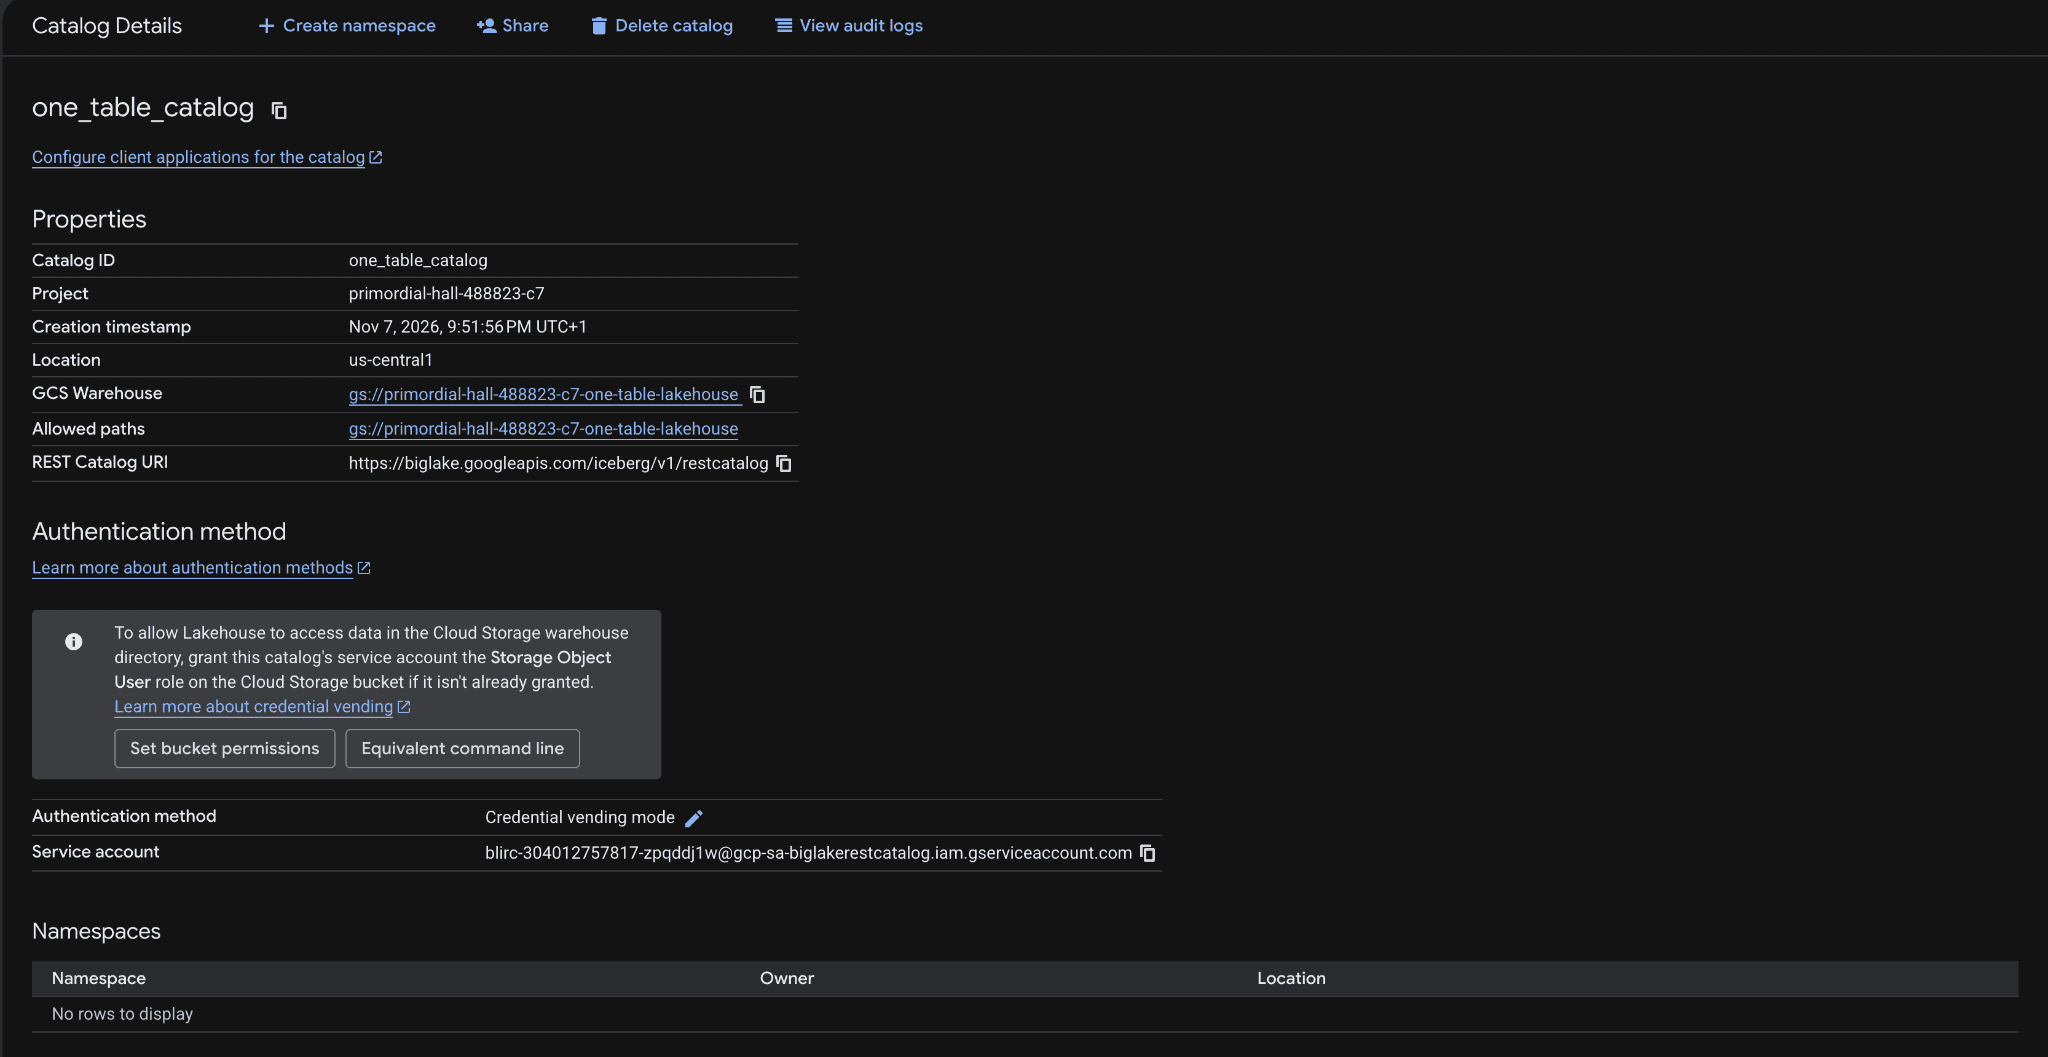
Figure 2. Project catalog details.
Step 2: Creating and Loading the Table from Managed Service for Apache Spark
Spark is up first because I am using it to create the table, and the table’s write settings need to exist from the first commit. Changing write modes on a table that other engines already write to is how you end up with a mix of file layouts you didn’t plan for.
One cluster runs both engines. Trino is an optional component on the same Managed Service for Apache Spark cluster:
gcloud dataproc clusters create one-table-cluster \
  --project=${PROJECT_ID} --region=${REGION} --zone=${REGION}-a \
  --image-version=2.3-debian12 \
  --optional-components=ICEBERG,TRINO \
  --enable-component-gateway \
  --master-machine-type=n2-standard-4 --worker-machine-type=n2-standard-4 \
  --num-workers=2 \
  --properties="dataproc:dataproc.lakehouse.catalog.${CATALOG_ID}=projects/${PROJECT_ID}/catalogs/${CATALOG_ID}"
The cluster’s default service account needs the following roles on the project:
roles/dataproc.workerroles/biglake.editorroles/serviceusage.serviceUsageConsumer
The cluster requires nothing on the bucket, because the catalog vends it a token.
That dataproc.lakehouse.catalog property wires Spark to the catalog in one line. It sets Spark’s warehouse to gs://<bucket>. On older 2.3 image builds, it sets Spark warehouse to gs://BUCKET. With the Apache Iceberg REST catalog endpoint, a gs:// warehouse URI addresses a single-bucket catalog named after the bucket, so my first Spark run wrote the table into a single-bucket catalog that Lakehouse had quietly created, and BigQuery could not find it under my multiple-bucket catalog. A multiple-bucket catalog is addressed as bl://projects/PROJECT_ID/catalogs/CATALOG_ID. It was a quick fix to the warehouse on the master node once the cluster was up:
gcloud compute ssh one-table-cluster-m --zone=${REGION}-a --command="sudo sed -i \
  's#^spark.sql.catalog.${CATALOG_ID}.warehouse=.*#spark.sql.catalog.${CATALOG_ID}.warehouse=bl://projects/${PROJECT_ID}/catalogs/${CATALOG_ID}#' \
  /etc/spark/conf/spark-defaults.conf"
If gcloud biglake iceberg catalogs list shows a catalog of type CATALOG_TYPE_GCS_BUCKET that you never created, this is why.
Now the table. Spark SQL, submitted as a job:
CREATE NAMESPACE IF NOT EXISTS one_table_catalog.shop;CREATE TABLE one_table_catalog.shop.orders (
order_id BIGINT,
customer_id BIGINT,
status STRING,
amount DECIMAL(10,2),
updated_at TIMESTAMP
)
USING iceberg
TBLPROPERTIES (
'format-version' = '2',
'write.delete.mode' = 'copy-on-write',
'write.update.mode' = 'copy-on-write',
'write.merge.mode' = 'copy-on-write',
'gcp.biglake.bigquery-dml.enabled' = 'true'
);
INSERT INTO one_table_catalog.shop.orders VALUES
(1001, 501, 'pending', 49.99, TIMESTAMP '2026-11-01 09:15:00'),
(1002, 502, 'paid', 120.00, TIMESTAMP '2026-11-01 10:42:00'),
(1003, 501, 'shipped', 18.50, TIMESTAMP '2026-11-01 11:05:00'),
(1004, 503, 'pending', 75.25, TIMESTAMP '2026-11-02 08:30:00'),
(1005, 504, 'paid', 260.00, TIMESTAMP '2026-11-02 13:20:00');gcloud dataproc jobs submit spark-sql --cluster=one-table-cluster --region=${REGION} \
--file=sql/spark/01_create_and_load.sqlThe three write.*.mode settings are the ones that matter. copy-on-write means an UPDATE, DELETE, or MERGE rewrites the affected data files instead of adding delete files beside them. BigQuery Data Manipulation Language (DML) (gcp.biglake.bigquery-dml.enabled = true) on these tables requires copy-on-write, and so does Google automatic table maintenance (gcp.biglake.table-management.enabled = true) for compaction and snapshot expiration. The last property switches on BigQuery writes, which are in Preview for Apache Iceberg tables in the Lakehouse runtime catalog.
The job finished in under 10 seconds of actual work. SHOW TBLPROPERTIES confirmed all three modes as copy-on-write, and five rows came back.
Step 3: Appending and Querying from Trino
Trino gets one job in this setup: read and append. It never updates or deletes rows. The open source Trino Iceberg connector writes row-level changes as merge-on-read, which means position delete files next to the data. Google BigQuery DML and automatic table maintenance require copy-on-write for DELETE, UPDATE, and MERGE. This means that row-level changes belong to Spark and BigQuery, and Trino sticks to INSERT and SELECT. For an orders table, that’s a natural split anyway: new orders arrive as appends, status changes are upserts.
With that division of labor in place, Spark creates the table and handles row-level changes alongside BigQuery, while Trino appends new orders and queries the same shared table.