Data Science
Data From 100 AI Agents Shows They Fail by Silent Drift
Analysis of 109 production AI agents shows quality and cost problems surface first. Errors fire last, if at all.
Analysis of 109 production AI agents shows quality and cost problems surface first. Errors fire last, if at all.
Google's Gemini 4 Hydrogen targets fast coding and agentic work. We tested it on audio transcription, video cataloguing, and PDF rule reasoning.
JEV now processes images and adds a Box primitive. Four Python examples cover classification, sharpness scoring, cropping and spotting differences.
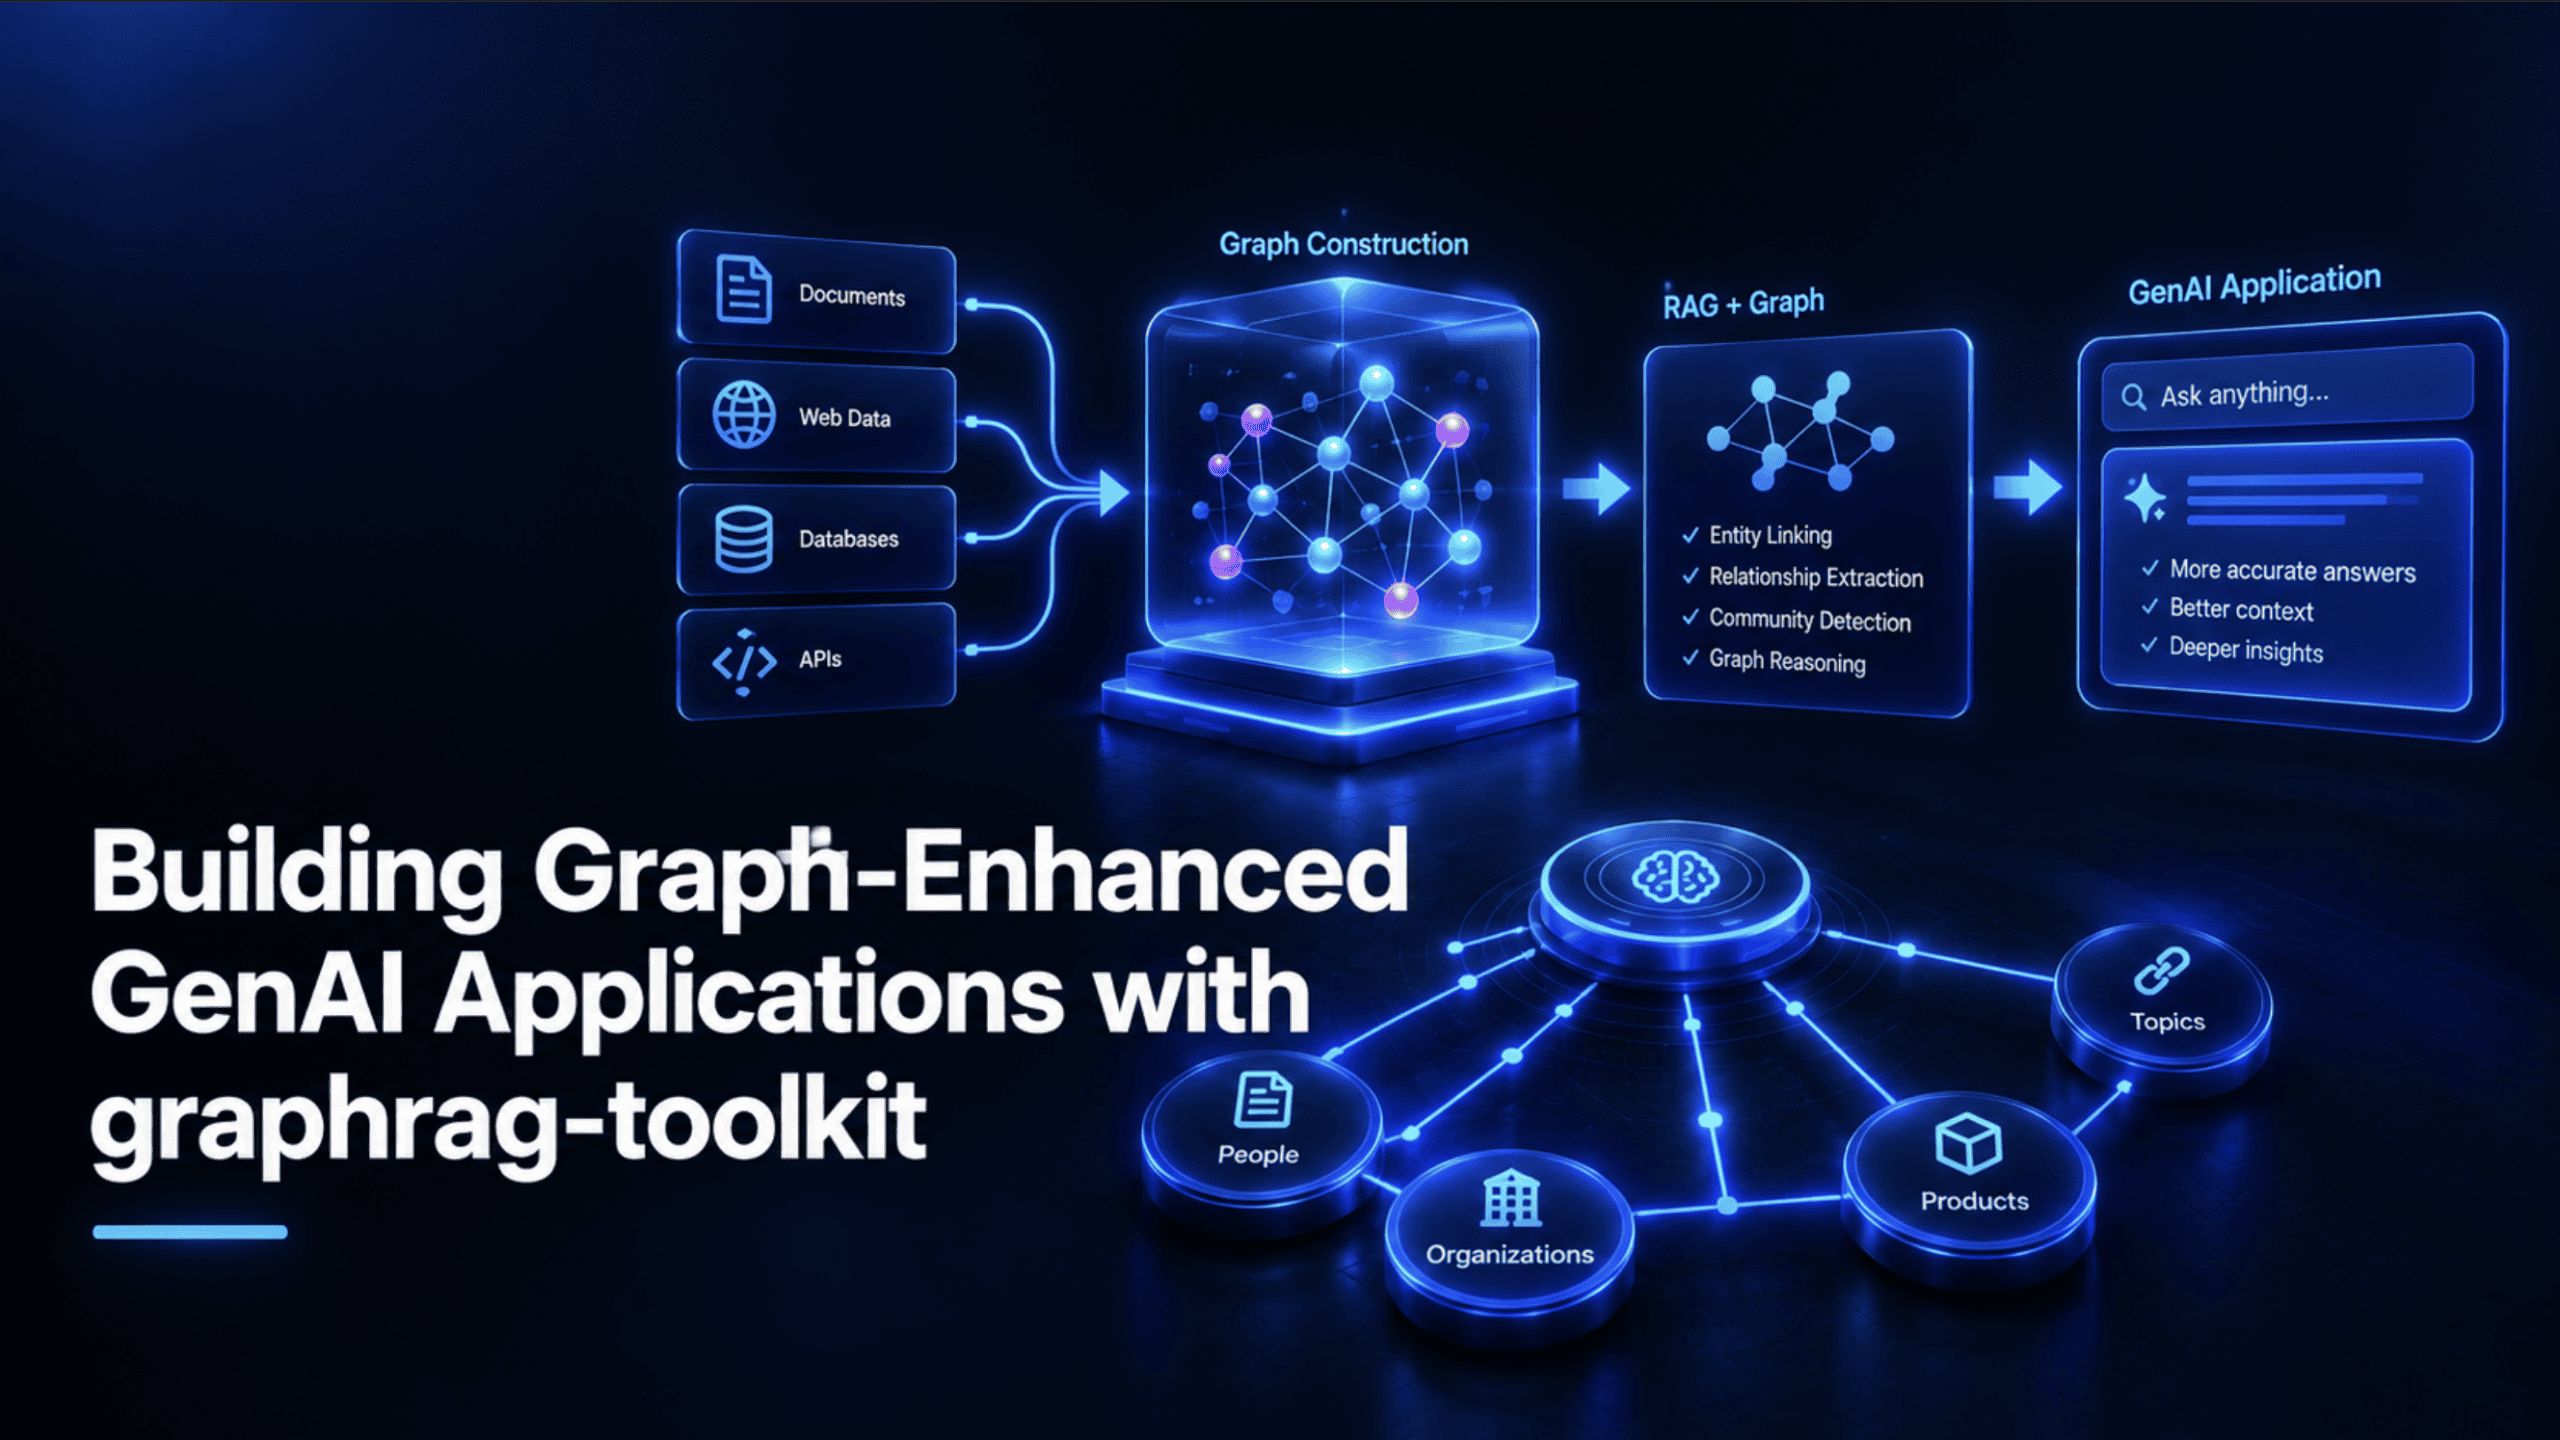
Plain vector RAG struggles with multi-hop questions. AWS Labs' graphrag-toolkit builds a knowledge graph to connect the dots.
BM25 barely slipped at 1,801 papers. A 2.68M-passage Wikipedia test changed the picture for RAG retrieval.
Learn how uv simplifies Python environment management compared to venv and pip, with faster dependency resolution, lockfiles, and project workflow tools in one.
Build an expected field-goal model in Python to separate shot selection from shot making, and better evaluate NBA shooting performance.
Automation may render employment obsolete. One proposed solution: a structured, paid system of human activities called the Omni-Game economy.
AI engineers increasingly call APIs rather than train models, making environmental impact harder to track. Here's how to measure it systematically.
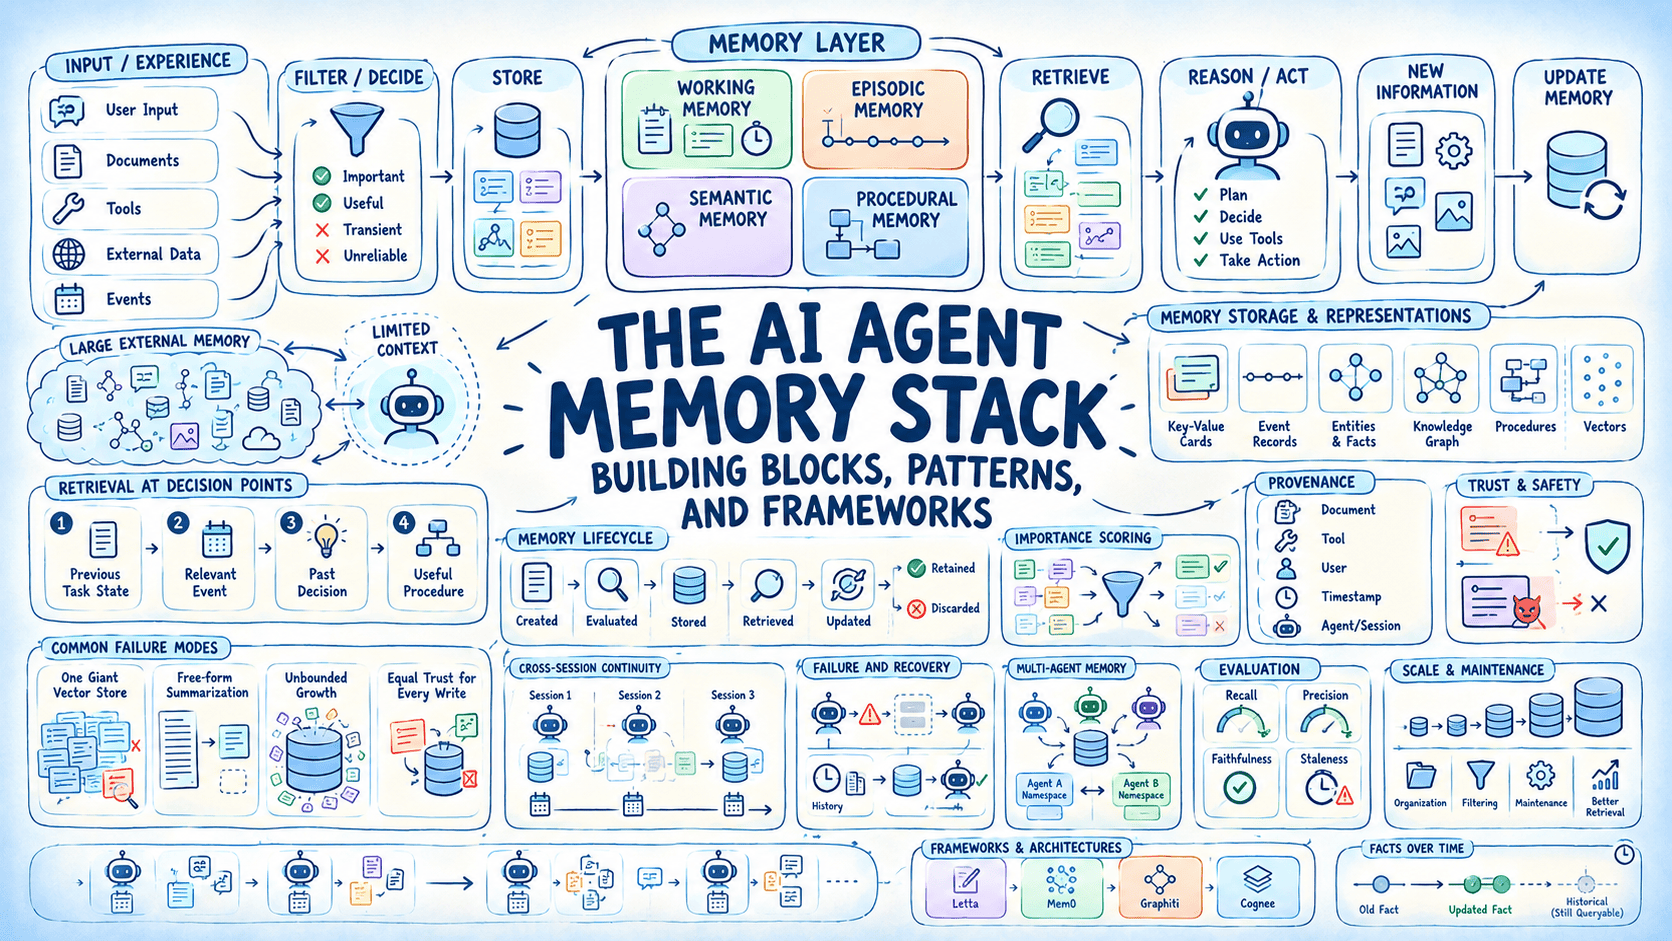
Learn the core AI agent memory types and design strategies. See how Letta, Mem0, Graphiti, and Cognee handle storage and changing facts.
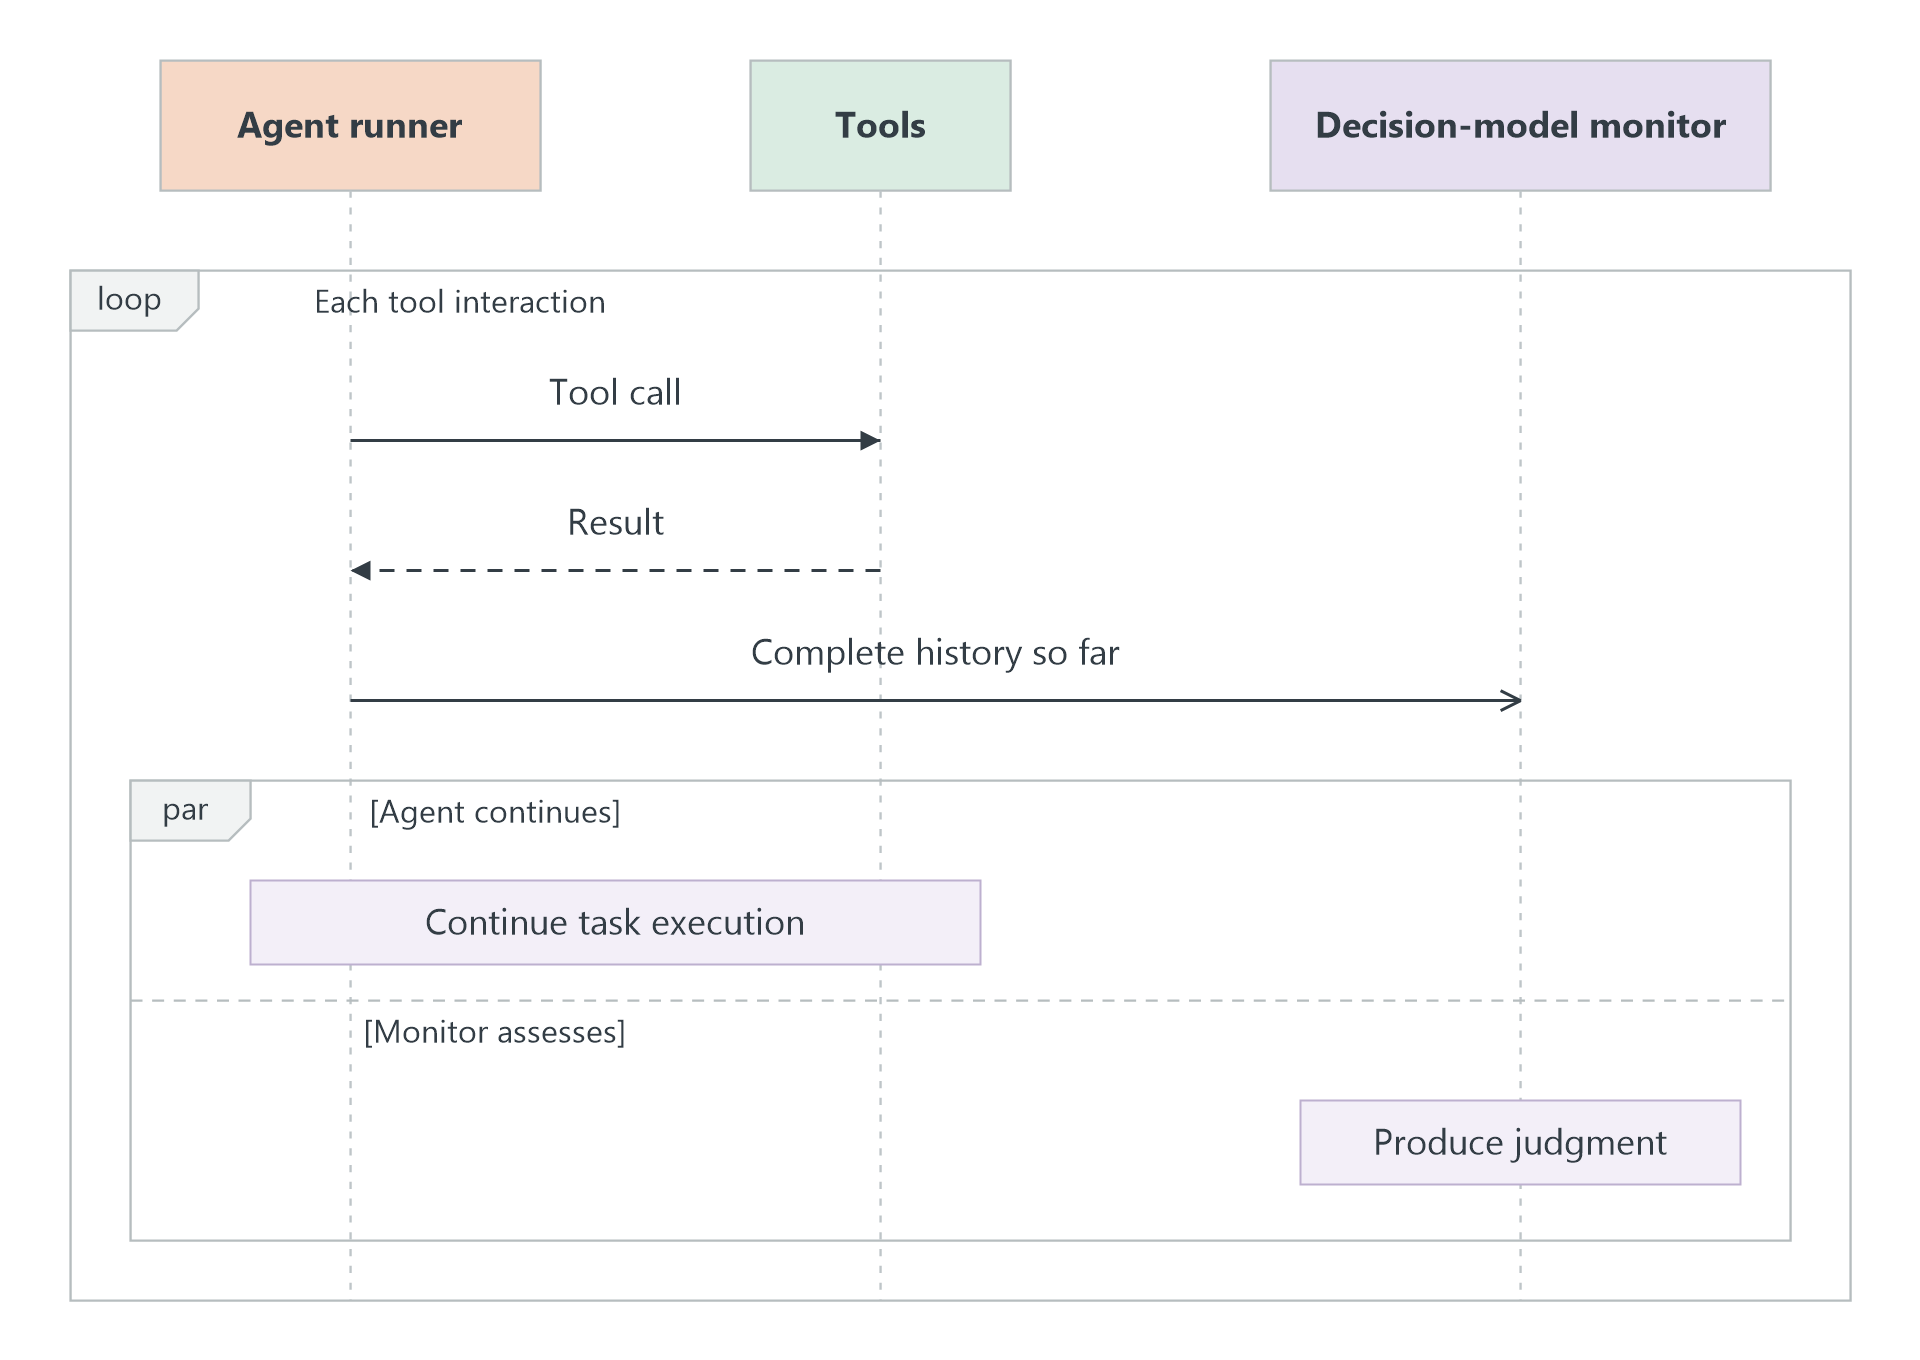
LLM agents can fail with real consequences. This article shows how to build a decision-model monitor that detects anomalous agent behavior as it unfolds.