Building Graph-Enhanced GenAI Applications with AWS Labs' graphrag-toolkit
Plain vector RAG struggles with multi-hop questions. AWS Labs' graphrag-toolkit builds a knowledge graph to connect the dots.
A standard retrieval-augmented generation (RAG) chatbot handles “what does the return policy say” without any trouble: it finds the chunk, hands it to the model, and it’s done. Ask it something like “how does the return policy interact with the warranty terms for international orders,” and it starts to wobble. That answer isn’t sitting in any single chunk. It requires connecting two separate pieces of the document that were never near each other in the source text, and a vector search that only measures how similar each chunk sounds to the question has no way to make that connection on its own.
That specific gap — a system that finds relevant text but can’t follow relationships between pieces of it — is exactly what graph-enhanced retrieval exists to close. This article walks through what that actually means, introduces AWS Labs’ open-source graphrag-toolkit, and then builds a real, working graph-enhanced research assistant from scratch, with every piece of code checked directly against the toolkit’s own documentation rather than assumed from memory.
What Graph-Enhanced Generative AI Applications Actually Are
Graph-enhanced RAG, usually shortened to GraphRAG, is retrieval that queries a knowledge graph rather than a plain vector index, so an application can follow actual relationships between pieces of information instead of only finding text that sounds similar to the question. Neo4j’s own explainer frames this as combining the retrieval strengths of a knowledge graph — explicit entities and the relationships between them — with the generative fluency of a large language model (LLM), so the model reasons over connected facts rather than isolated fragments of text.
This isn’t a single vendor’s marketing framing. Oracle’s own write-up on the same idea makes essentially the same case from a completely different part of the database industry: standard RAG treats every chunk as an independent island, while a graph captures how those islands actually connect, which entities appear in multiple places, and how concepts relate across an entire document collection rather than within one paragraph at a time. Two major database companies converging independently on the same core argument is a reasonable signal that the underlying problem is real, not a talking point invented to sell graph databases.
Where Plain Vector RAG Actually Falls Short
It’s worth being precise about the mechanism here rather than just gesturing at “vector search isn’t perfect.” A standard vector store retrieves chunks purely based on semantic similarity between the embedded question and the embedded chunks, and it does that retrieval for each chunk in isolation. There’s no representation anywhere in that process of how one chunk relates to another: whether they discuss the same entity, whether one provides context the other depends on, or whether they sit in a cause-and-effect relationship.
Multi-hop questions — ones that require two or three separate, connected facts assembled together before an answer makes sense — are exactly where this breaks down. And it’s a structural limitation of the retrieval mechanism itself, not something better prompting or a larger context window can reliably fix. The problem isn’t that the model can’t reason once it has the right information; it’s that plain vector search often never surfaces all the right pieces in the first place.
Introducing graphrag-toolkit
The graphrag-toolkit is an open-source, Apache 2.0-licensed Python toolkit built by AWS Labs specifically to close that gap. It’s made up of two components. The first, and the focus of this article, is lexical-graph, a framework for automatically building a hierarchical knowledge graph from unstructured documents and querying it. The second, BYOKG-RAG (Bring Your Own Knowledge Graph), is a separate approach for teams that already have a knowledge graph and want a multi-strategy question-answering layer over it, without re-extracting anything from scratch.
AWS introduced the toolkit publicly in its own launch blog post, and the design behind the hierarchical lexical graph model is documented in a dedicated research paper, “Hierarchical Lexical Graph for Enhanced Multi-Hop Retrieval.” It’s also not purely theoretical: Deloitte uses the lexical-graph inside its Amazon Neptune-based GenAI Security Intelligence Center, a real production deployment covered in a re:Invent 2025 technical session.
How It Actually Works
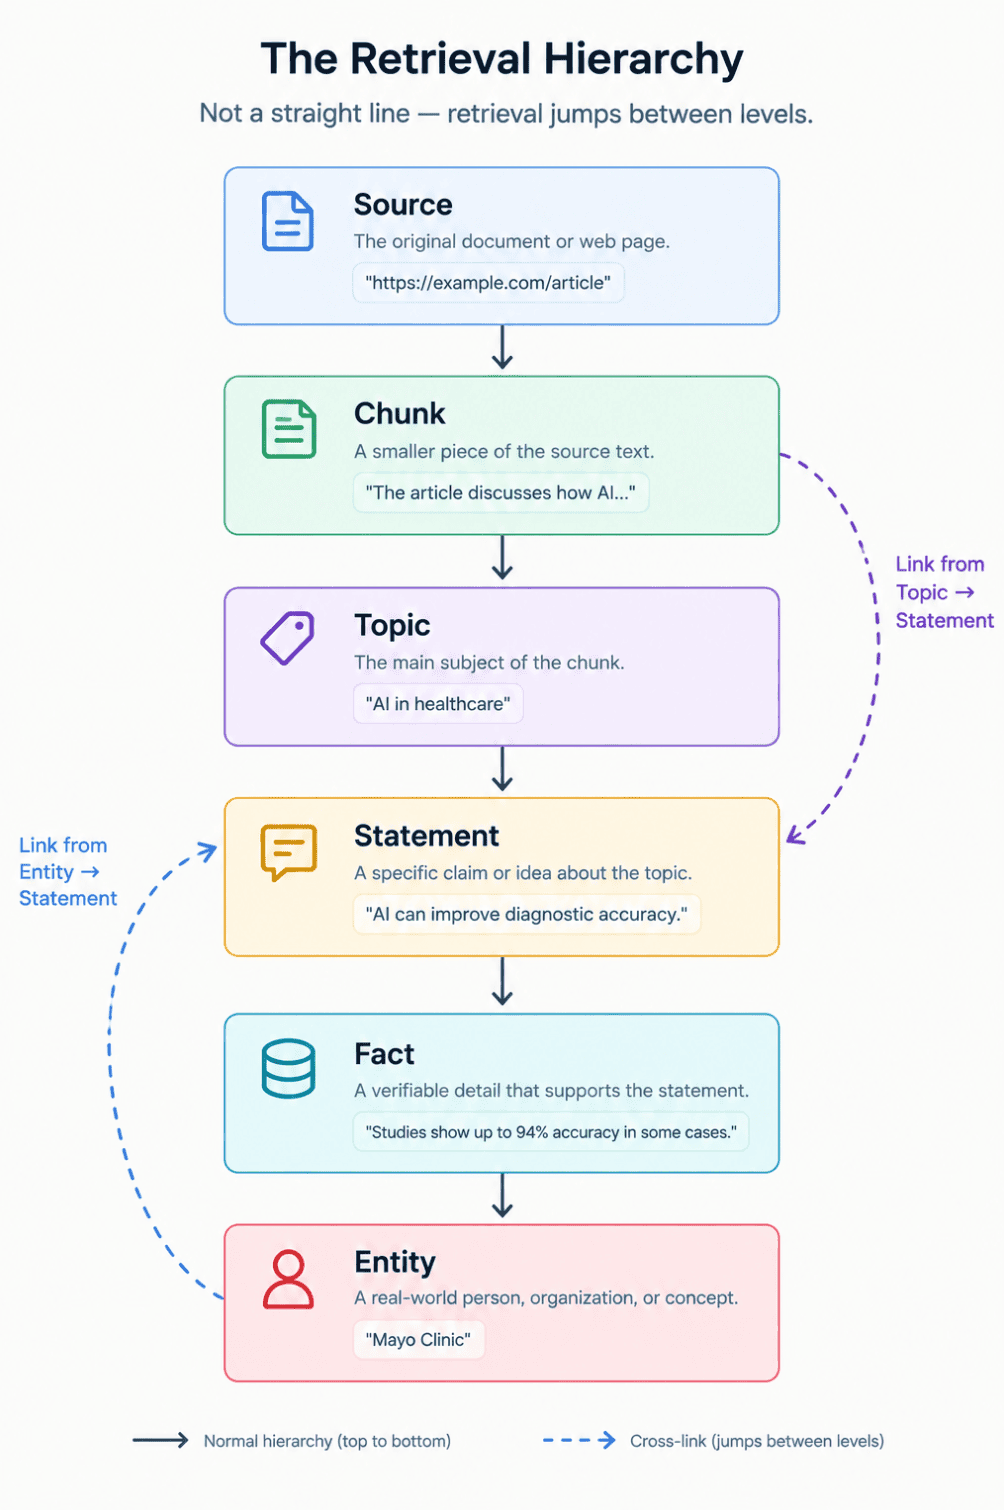
This is the technical core worth understanding before writing any code. Per the toolkit’s own graph model documentation, a lexical graph organizes extracted content into six connected levels: source, chunk, topic, statement, fact, and entity. Retrieval can hop between any of these levels rather than being stuck retrieving only at the chunk level the way a plain vector store is, which is the structural feature that makes multi-hop questions actually answerable.
Building that graph happens in two distinct stages, extract and build, and they’re deliberately kept separate. The extract stage ingests raw source documents, chunks them, and uses an LLM to pull out topics, statements, facts, and entities. The build stage takes those extracted elements and populates the actual graph and vector indexes from them. Running these as two genuinely separate, micro-batched, resumable pipeline stages, rather than one monolithic process, means a large ingestion job can be paused, inspected, or filtered partway through without losing progress.
One detail is worth knowing specifically, because it explains why extraction quality holds up as well as it does: the process makes two separate LLM calls per chunk rather than one. The first call cleans up the raw chunked text into a set of well-formed, self-contained propositions. The second call then extracts topics, statements, facts, and entities from those cleaned propositions rather than from the messier raw text directly. That extra step is optional (the second call can run directly against raw content), but per the toolkit’s own documentation, extraction quality measurably improves when the proposition-cleanup pass runs first.
Querying: Traversal-Based Search
Here’s the actual query mechanism, sourced directly from the toolkit’s querying documentation. A user’s question first gets embedded, and that embedding runs a top-K similarity search against the vector store to find anchor points: statements or chunks that look relevant on the surface. Those anchors then seed one or more graph traversal queries, which pull in thematically connected content from across the graph, not just the chunks that scored highest on similarity alone. The retrieved content, grouped by topic and source, is then supplied to an LLM alongside the original question to generate the actual answer.
One genuinely current fact is easy to miss: the toolkit also ships an older semantic-guided search strategy, but the documentation states directly that it’s likely to be retired in a future release. Traversal-based search is both the current default and the one worth building against today, which is exactly the approach used in the hands-on build below.
Before writing any code, it’s worth knowing what’s actually swappable in this toolkit and what isn’t, since the choice affects both cost and setup complexity.
| Layer | Built-in options |
|---|---|
| Graph store | Amazon Neptune Database, Amazon Neptune Analytics, Neo4j, FalkorDB |
| Vector store | Amazon Neptune (DB and Analytics), Amazon OpenSearch Serverless, Postgres (with pgvector), Amazon S3 Vectors |
| Foundation model provider | Amazon Bedrock (the only built-in option; extensible to other providers with custom work) |
Neo4j and Postgres with pgvector are the two options that can run entirely locally in Docker at zero infrastructure cost, which is exactly why this tutorial builds around that combination. One small caveat on FalkorDB specifically: the toolkit’s repository keeps FalkorDB support in a separate lexical-graph-contrib/falkordb package rather than bundling it into the core graphrag-lexical-graph install, so you need that additional package if you go that route instead of Neo4j. The one piece that can’t currently be swapped out without extra engineering effort is the model provider: Amazon Bedrock is what the toolkit is configured to use by default, so an AWS account with Bedrock model access enabled is unavoidable for this build, even though the graph and vector stores themselves won’t touch AWS at all.
Prerequisites
Exactly what’s needed before starting:
- Python 3.10 or later
- Docker installed and running (for local Neo4j and Postgres)
- An AWS account with access enabled to at least one Amazon Bedrock foundation model, since that’s the one dependency this tutorial genuinely can’t route around given the toolkit’s current design
Building a Graph-Enhanced Research Assistant
The goal: a small research assistant that can answer questions spanning multiple real Wikipedia articles about human spaceflight — specifically, questions a single article alone can’t fully answer, exactly the kind of multi-hop case this article opened with.
Step 1: Spinning Up Local Neo4j and Postgres
# docker-compose.yml
services:
  neo4j:
    image: neo4j:5
    ports:
      - "7474:7474"
      - "7687:7687"
    environment:
      - NEO4J_AUTH=neo4j/graphrag-password

  postgres:
    image: pgvector/pgvector:pg16
    ports:
      - "5432:5432"
    environment:
      - POSTGRES_PASSWORD=graphrag-password
      - POSTGRES_DB=graphrag
Run docker compose up -d and both databases are live: Neo4j on its standard Bolt port 7687, and Postgres on port 5432. With the graph store and the vector store both running locally at no cost, the infrastructure the lexical-graph needs is in place, and only the Bedrock model access remains as an AWS dependency.