The AI Agent Memory Stack: Building Blocks, Patterns, and Frameworks
Learn the core AI agent memory types and design strategies. See how Letta, Mem0, Graphiti, and Cognee handle storage and changing facts.
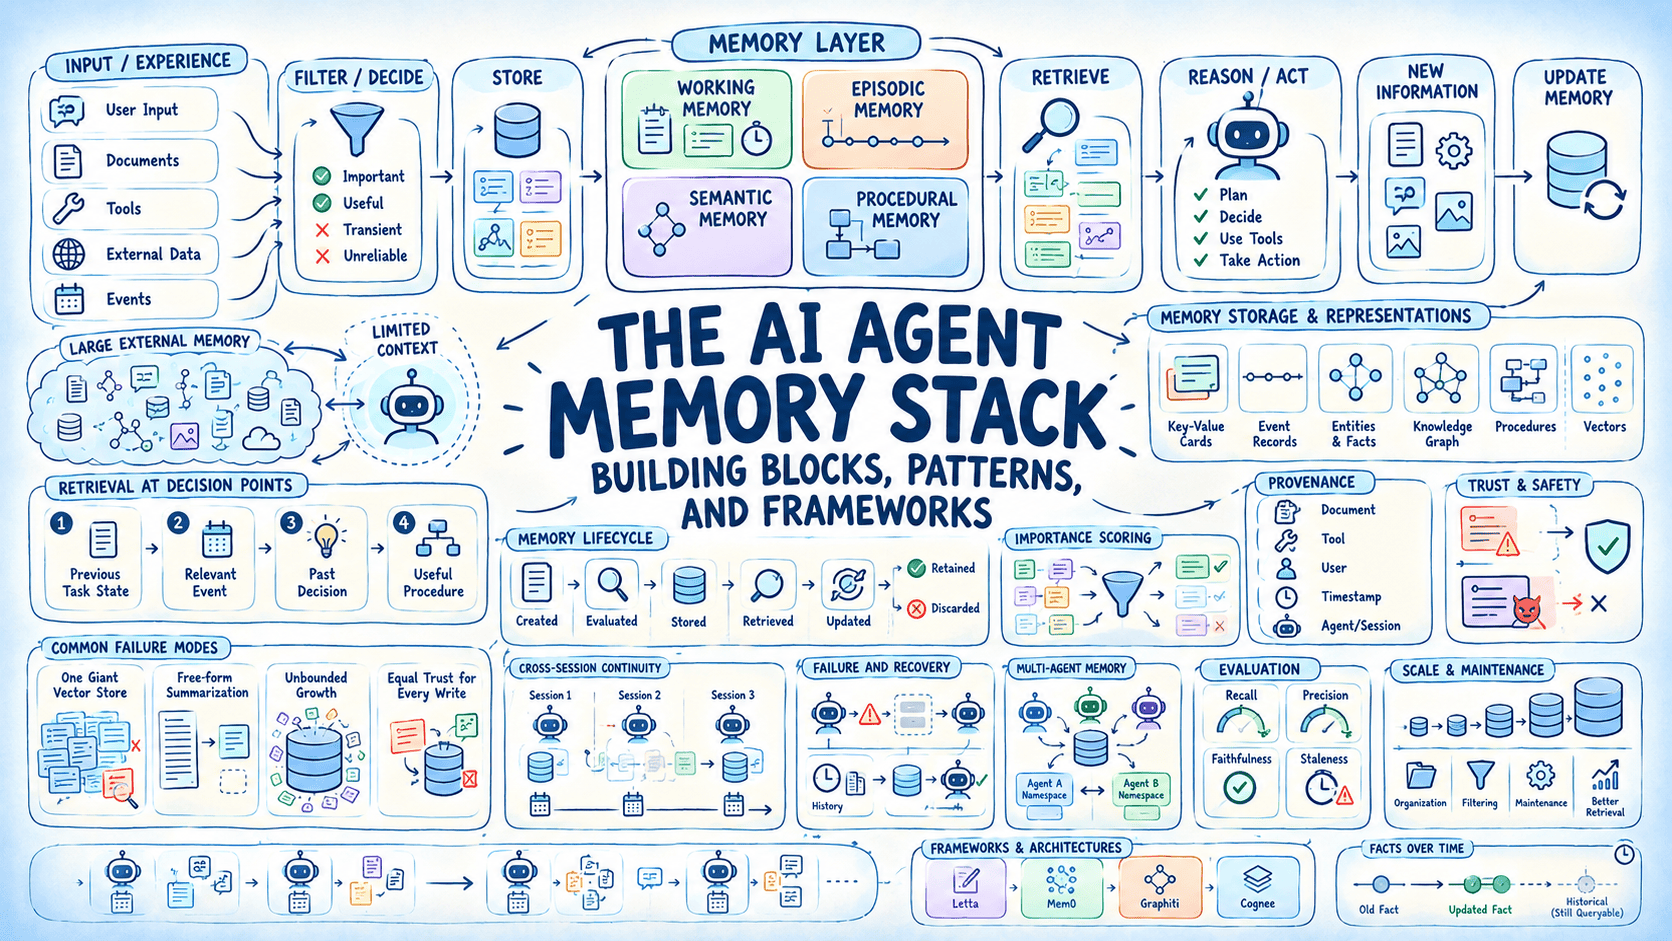
In this article, you will learn how agent memory works, what types of memory exist, and how different frameworks approach storage, retrieval, and memory management at scale.
Topics we will cover include:
- The core memory types used in AI agents and what each one is designed to store.
- Practical design strategies for writing, retrieving, and maintaining agent memory reliably.
- How leading memory frameworks differ in their storage models, retrieval approaches, and handling of fact changes over time.
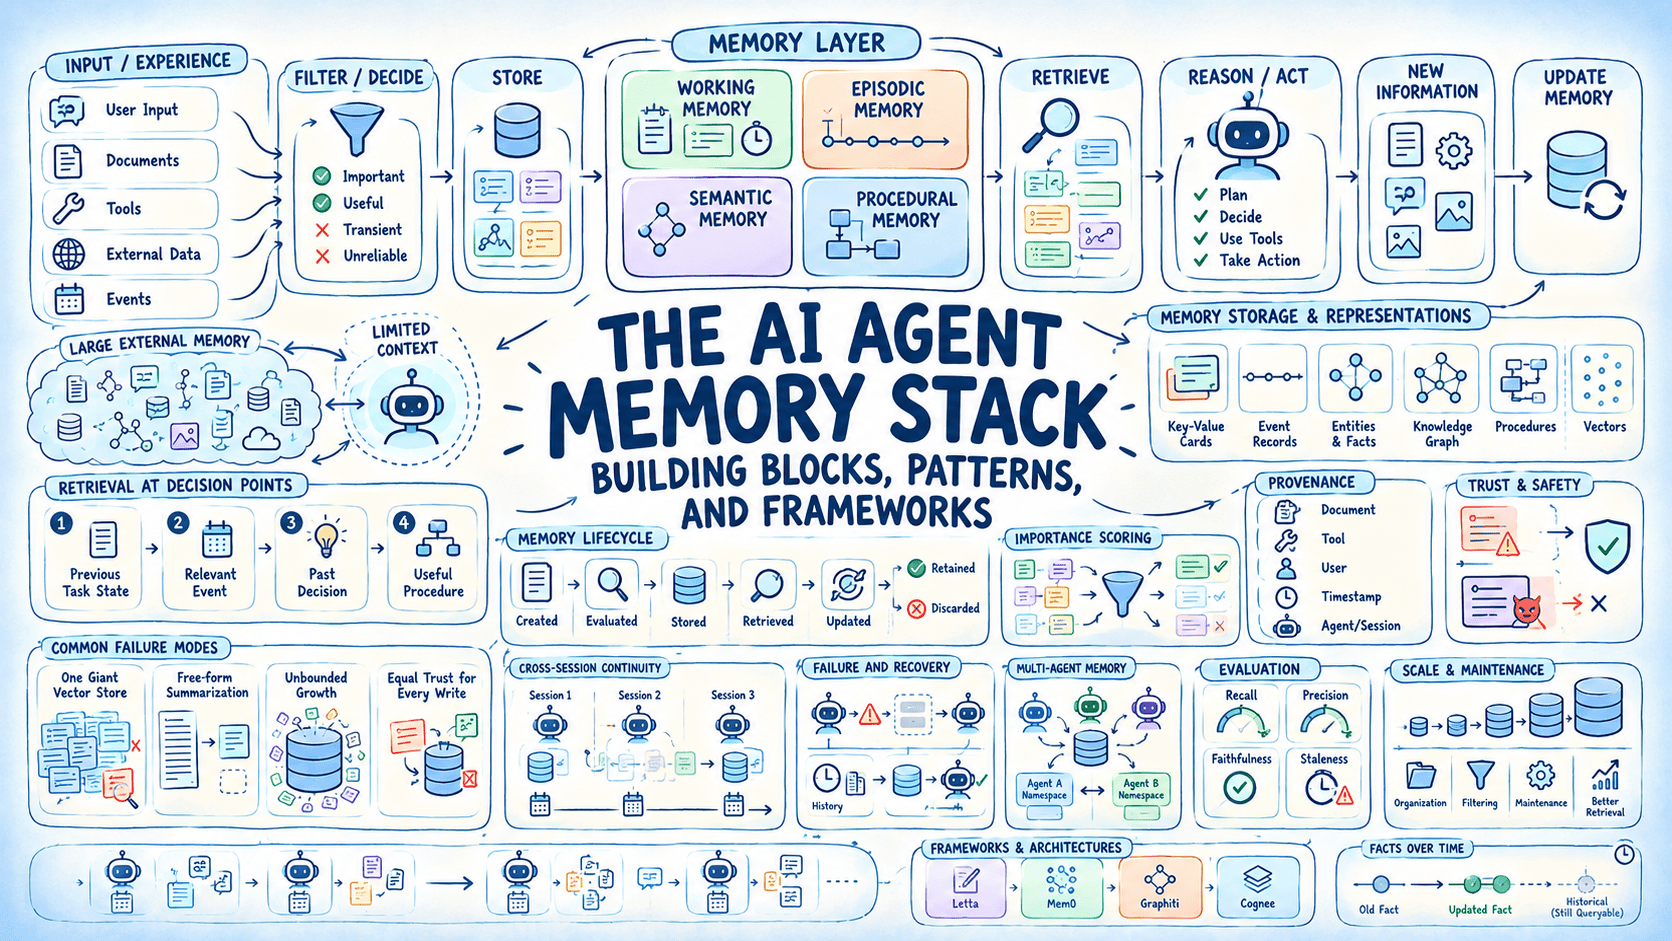
Introduction
A language model does not retain information between calls. Each time it runs, it works with the text provided in that request and does not automatically remember what happened before. This works well for simple, one-off questions, but AI agents need more when they have to track previous actions, remember user preferences, or continue a task across multiple steps.
Memory solves this by storing information outside the model’s context window and making it available when needed. But agent memory is not a single mechanism. Different types of memory serve different purposes, while different storage and retrieval patterns affect how reliably that information can be used. This article covers:
- The building blocks: what memory types exist and what each one is for
- How agents store, retrieve, and update information reliably
- How different frameworks handle memory storage, retrieval, and organization
We start with the building blocks.
The Building Blocks of Agent Memory
Before looking at memory frameworks and implementation patterns, it helps to define what agent memory needs to store. Different tasks require different kinds of information, and each type of memory has its own role, storage model, and retrieval strategy.
Why Agents Need Memory at All
Agents often need to carry information across calls and tasks. They may need to remember what has already been scheduled to avoid duplicate actions, retain a user’s preferences across sessions, or carry forward information discovered during a multi-step task. They may also need to remember failed approaches so they do not repeat the same work.
Without memory, each call starts with only the information in its current context. The agent has no reliable way to know what happened before or what it has already learned.
Agent Memory Types
Agent memory falls into the following types, each suited to a different kind of information and retrieval pattern.
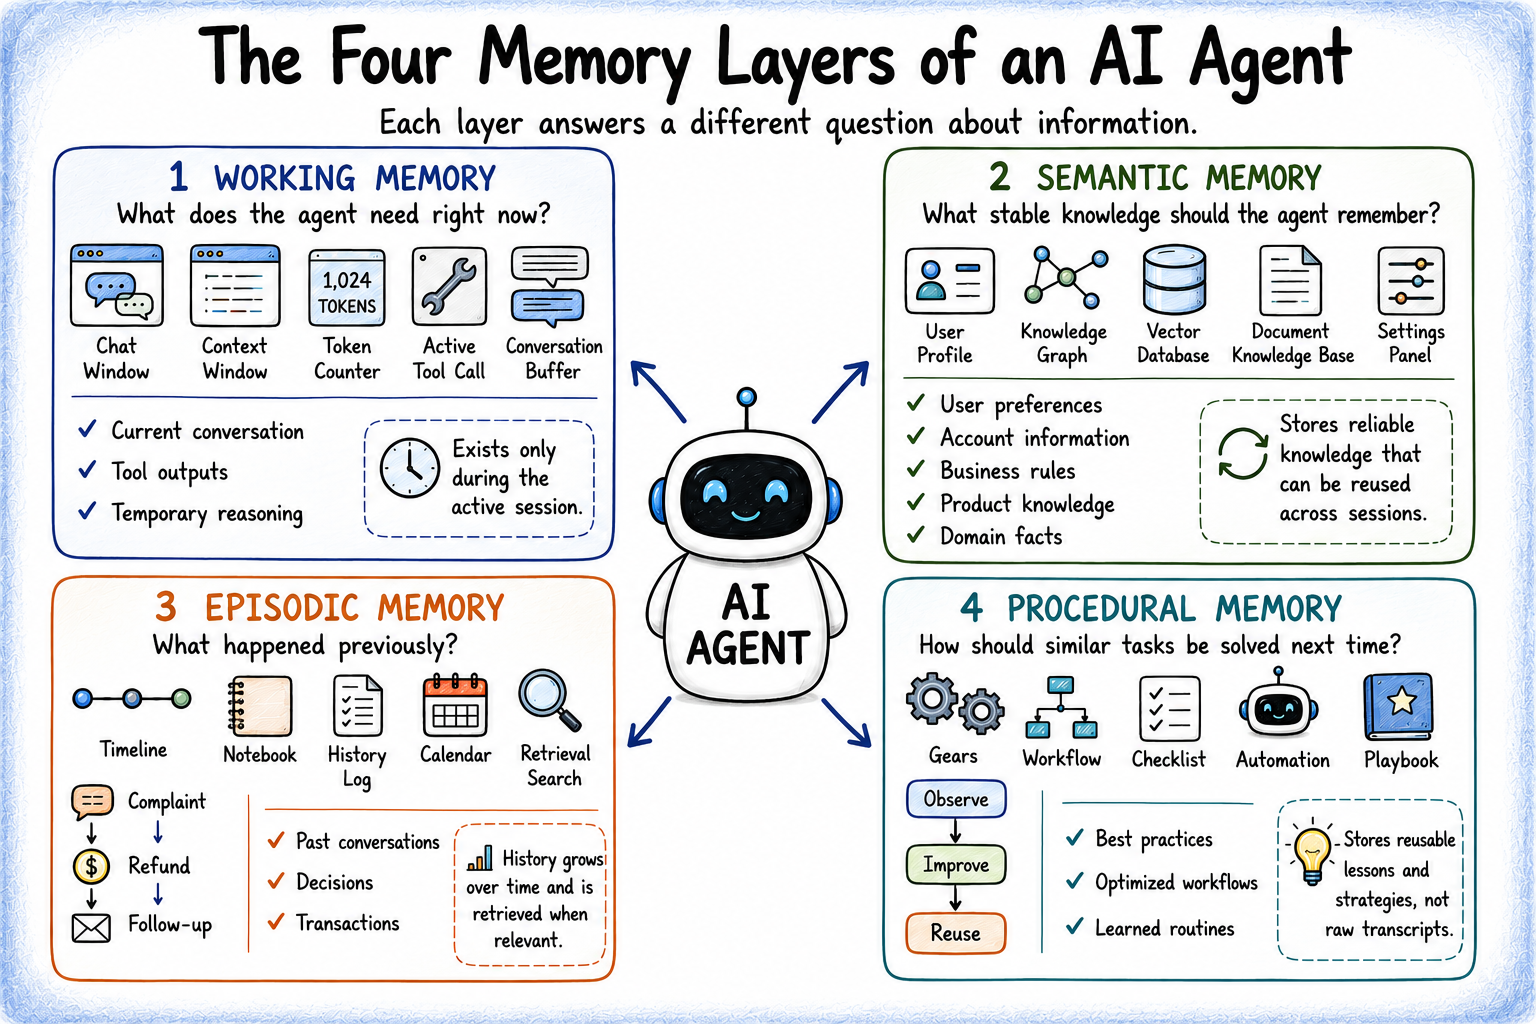
The table below shows what each memory type holds, where it is typically stored, and how it is retrieved:
| Memory Type | What It Holds | Storage Layer | Retrieval Method |
|---|---|---|---|
| Working | Active task state: intermediate results, scratchpad values | In-memory or short-lived key-value store | Direct lookup by key |
| Episodic | What happened: past interactions, task runs, decisions made | Time-ordered log or vector store | Semantic similarity search |
| Semantic | What is true: facts and preferences that get updated rather than appended | Key-value or entity store | Exact lookup by attribute, sometimes combined with semantic search |
| Procedural | How to do things: successful action patterns, known failure modes | Prompt templates or fine-tuning | Pattern match or direct injection |
Working memory is the information currently available in the context window. The other memory types determine what information should be brought into that context. Episodic memory captures past events, while semantic memory stores facts about entities, users, or the environment. Keeping these distinctions clear makes memory easier to store, retrieve, and maintain.
Agent Memory Design Strategies
Knowing the different memory types is only the starting point. The more substantial part is deciding what should be stored, when it should be written, how long it should remain, and when it should be retrieved. These decisions determine whether memory stays useful as an agent runs longer tasks and accumulates more information.
A Worked Example: A Multi-Step Research Agent
Consider a research agent working on a task over several days: gathering sources, extracting claims, drafting sections, and repeating the process.
After each step, the agent writes the result to working memory with a short expiry. Each entry is tagged with basic metadata, such as the tool that produced it and the session it belongs to. When a result proves useful, it can be promoted to episodic memory with an importance score. A temporary observation may be discarded, while a decision that affects later steps can be retained.
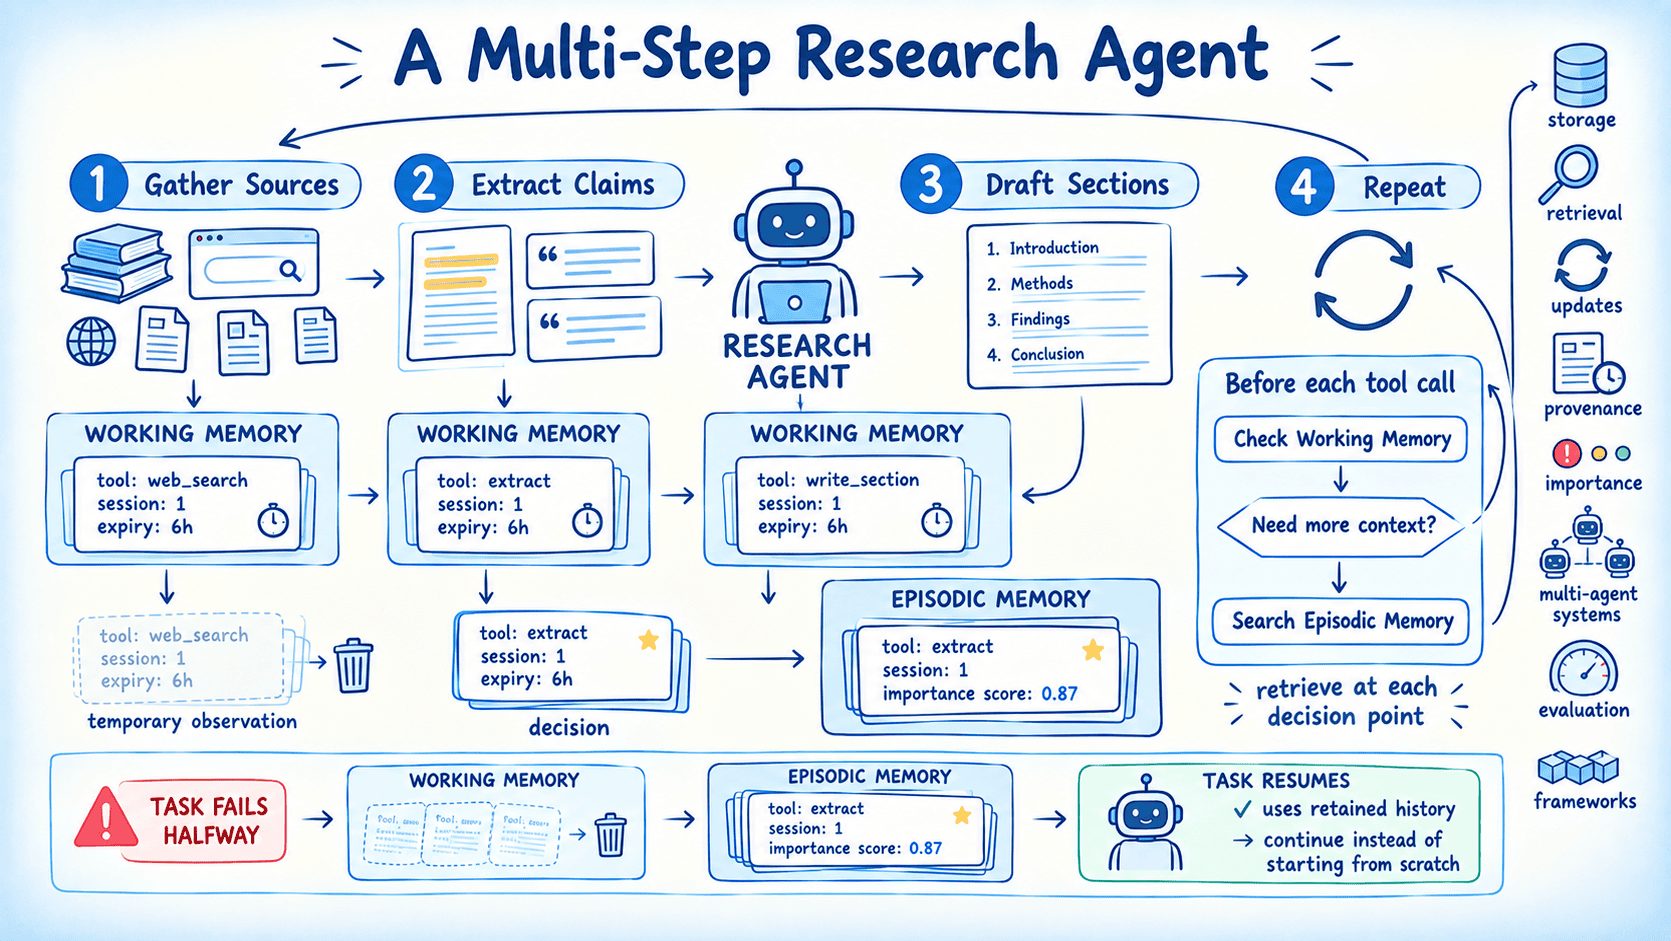
Before each tool call, the agent checks working memory for relevant state and then searches episodic memory when additional context is needed. Retrieval happens at each decision point rather than only once at the beginning, because the information that matters can change as the task progresses.
If the task fails halfway through, the agent can discard the temporary working state while retaining the episodic record of completed work. When the task resumes, it can use that history instead of starting from scratch.
Memory Design Strategies That Work
A few practices consistently make memory systems more reliable as they grow:
- Score memory importance before writing: Filter out transient observations and low-value tool outputs so the store stays focused on information that is likely to matter later.
- Scope memory by agent role: In multi-agent systems, keep each agent’s memory focused on its responsibilities to reduce irrelevant or conflicting information.
- Retrieve at decision points: Refresh context throughout a workflow instead of retrieving memory only when the task starts.
- Track provenance: Record where each memory came from, such as the agent, tool, user input, or timestamp. This makes memory easier to debug and audit.
Together, these practices help keep memory relevant as tasks become longer and the amount of stored information increases.
Memory Design Strategies That Don’t Always Work
Some approaches are simple to implement but become unreliable as the memory store grows. The table below covers common approaches and the problems they introduce:
| Approach | Why It Fails |
|---|---|
| Embedding everything into one vector store | Retrieves information that is semantically similar but not necessarily relevant to the task, while making relationships between facts difficult to represent. |
| Free-form summarization as memory compression | Can remove specific details, constraints, or numbers that become important later, and may preserve an incorrect statement as if it were verified. |
| Unbounded memory growth with no maintenance | Causes irrelevant entries to compete with useful ones, reducing retrieval quality while increasing storage and maintenance costs. |
| Trusting every write equally | Creates a risk of memory poisoning, where untrusted or adversarial content is stored and later treated as reliable information. |
The common problem is treating memory as one undifferentiated store. Reliable systems instead separate memory by purpose, apply different retrieval rules, and track how much each stored item should be trusted.
We have a more detailed AI Agent Memory Design: What Works and What Doesn’t article you can check out if you are interested.
Memory Frameworks and Architecture at Scale
The patterns above are implementation-agnostic. In practice, they are built on top of memory frameworks that make different choices about storage, retrieval, structure, and maintenance.
⚠️ The frameworks mentioned in this section are not an exhaustive list of everything available. Instead, they provide a useful overview of several important approaches to agent memory and the tradeoffs behind them.
For a broader look at the agent memory framework landscape, see our agent memory frameworks round-up.
How Memory Frameworks Differ
These frameworks sit at different points between flat, text-based memory and structured knowledge graphs. That choice affects how related facts are retrieved, how relationships are represented, and how changes to stored information are handled.
| Framework | Memory Model | Handles Fact Changes By |
|---|---|---|
| Letta | Self-editing text blocks that the agent can rewrite directly | The model identifies a contradiction and updates the block |
| Mem0 | Vector-based memory with entity-aware retrieval | New memories are added and retrieved alongside existing ones |
| Graphiti | Bi-temporal knowledge graph with typed relationships between entities | Invalidating older relationships while keeping their history queryable |
| Cognee | Extraction pipeline that builds graph, vector, and relational layers from source data | Rebuilding the memory representation, with temporal modes for tracking changes |
If you are interested in going deeper into how different frameworks approach storage, retrieval, and memory management, check out Agent Memory Systems and Knowledge Graphs: Letta, Mem0, Graphiti, and Cognee.
Frameworks differ mainly in how they organize stored information, represent relationships between facts, and handle changes over time. A simpler memory layer can work well when an agent mainly needs to retrieve relevant facts or recent context. More structured systems become useful when the agent needs to follow relationships between entities, reason across multiple facts, or preserve how information changed over time.
Conclusion
Agent memory is a stack of distinct components rather than a single mechanism. Working, episodic, semantic, and procedural memory each hold a different kind of information and call for their own storage and retrieval approach. Reliable systems score what they write, scope memory by role, retrieve at decision points, and track provenance, rather than pooling everything into one undifferentiated store. Frameworks such as Letta, Mem0, Graphiti, and Cognee make different tradeoffs along the spectrum from flat text memory to structured knowledge graphs, so the right choice depends on whether your agent mainly needs to recall relevant facts or to reason over relationships and how they change over time.