Conformal Prediction: Building Reliable ML Models with Uncertainty Intervals
Conformal prediction adds uncertainty intervals to ML predictions. Learn how to apply it step-by-step using Python and the UCI Online Shoppers dataset.
Every time anyone builds ML models, the focus quickly moves from overall numbers and highly technical measures of model health to how confident we are in each predicted result. In essence, can my model reliably deliver accurate results across the board? Aggregate metrics such as accuracy, recall, precision, R², and AUPRC/AUROC are often not enough to convince stakeholders of a model’s real-world performance — no matter how carefully they are explained.
This is where Conformal Prediction (CP) could help. In addition to a prediction, CP creates an interval around the prediction that quantifies uncertainty. Such uncertainty quantification through prediction intervals bridges the gap between technical measures of model performance and stakeholder trust. This makes conversations about model reliability far easier than relying on overall model health. For a detailed explanation of the math, see Vovk, Gammerman & Shafer, 2005. For a more accessible overview, check out Angelopoulos & Bates, 2022. Dancker, 2024 explains CP clearly, and Allen, 2023 offers a helpful Python code walkthrough.
The CP algorithm is an intuitive idea that is flexible across different predictive models (regression, boosting/bagging models, neural networks, etc.) and easy to apply without the help of any specialized machine learning packages. The CP algorithm wraps a statistical process around a predictive model to generate a prediction interval around each predicted value. Intuitively, the value of applying CP is to address the problem of prediction reliability — a probability of customer purchase of 77% is great, but what if this probability can be as low as 50% and as high as 97%? Such a wide band around the predicted probability makes the prediction less reliable, versus saying the predicted probability will fall between 70% and 85%.
You might be wondering why CP and not other well-known uncertainty quantification methods such as bootstrapping or dropout methods used for quantifying uncertainty in neural networks. There are three main reasons:
- CP does not require any particular model specification and works quite well for black-box models.
- It is computationally very cheap, especially when compared to bootstrapping, which relies on repeated resampling.
- Exchangeability: According to Vovk, Gammerman & Shafer, 1999, exchangeability ensures that calibration points (used to compute the prediction interval) and test points (used to evaluate the computed prediction interval) can be treated as if they come from the same distribution. As a result, the prediction intervals computed on the calibration set provide a valid coverage guarantee. If α proportion of calibration points fall outside the interval (and 1−α are inside) for the calibration set on average, then the same coverage level holds for the test points on average.
With these in mind, let’s walk through the algorithm using the publicly available Online Shoppers Purchasing Intention Dataset (Sakar & Kastro, 2018). This dataset is available in the UCI Machine Learning Repository and is licensed under the Creative Commons Attribution 4.0 International (CC BY 4.0) license, which permits commercial use. It is well-suited for this example, as it is a typical dataset for customer purchase prediction.
The CP algorithm requires the data to be split into three parts:
- Train set — to learn a model (e.g., classifier, neural network, etc.)
- Calibration set — to quantify the model’s uncertainty through conformal scores that enable the development of prediction intervals
- Test set — to evaluate the reliability of the model and its uncertainty quantification
A 70%/15%/15% split is used between the train, calibration, and test sets.
Step 1: Train the Model
Training begins with an XGBoost model on the online purchase intent dataset to understand the impact of all available features on the probability of purchase (Revenue = 1 indicates the user session resulted in an e-commerce purchase; 0 indicates no purchase). For a parsimonious representation of the CP algorithm, no additional feature engineering is performed here.
Before modeling, it is useful to examine the distribution of the Revenue variable to check for class imbalance.
 Figure 1: Plot for class imbalance
Based on the distribution shown in Figure 1, only 15% of the data points belong to the positive class (= 1), so imbalance treatment is required. For simplicity, weighted XGBoost is used here, although more rigorous approaches such as SMOTE or Random Undersampling are also valid options.
After fitting the model, examining the top 10 features by importance is informative.
 Figure 2: Plot for feature importance scores
Intuitively, the feature importance results make sense. The number of times the customer visited the webpage (PageValues) is the most important indicator of purchase decision, followed by month of purchase — November, for instance, may be driven by the Thanksgiving shopping period. Similarly, customers often visit the product page multiple times before deciding, which explains why VisitorType_Returning_Visitor also ranks highly.
Step 2: Calibrate the Model
Calibration measures how far predictions are from reality and enables the construction of prediction intervals around them. It consists of four parts:
- Predict probabilities on the calibration set p(x)
- Compute conformal scores — how far or close the predicted probability p(x) is to the true label (y). A simple and intuitive form is |y − p(x)|, where y is the true label (1 or 0). This ensures that a larger score corresponds to a prediction farther from the true label. Other options include inverse probability weights and normalized residuals, but absolute residuals are used here for simplicity.
- Choose an acceptable error tolerance α — the proportion of observations expected to fall outside the prediction interval. For example, α = 30% means 30% of predictions will fall outside the interval, and the interval will contain at least 70% of the true labels.
- Find the 1−α percentile (the 70th percentile in this example) of the conformal scores to obtain the conformal quantile (q), which is used to build confidence bands around predicted probabilities on the test data.
Table 1 below illustrates this with a simple example. For each customer, the predicted probability of purchase and the conformal score (difference from the true label) are calculated. If the conformal scores are sorted in ascending order — [0.1, 0.2, 0.25, 0.35, 0.4] — the 70th percentile value is 0.35, giving us the conformal quantile.
 Table 1: Illustrative example for calculating the conformal scores
Calibration gives us a quantile-based interval that determines how reliable predictions will be on unseen test data.
Step 3: Apply to the Test Set
Step 3a: Fixed Interval Approach
The conformal quantile derived in Step 2 is applied to predicted probabilities on the test set to generate prediction intervals. As established, the conformal quantile is 0.35. Table 2 below illustrates how the prediction interval is developed using predicted probabilities and the conformal quantile.
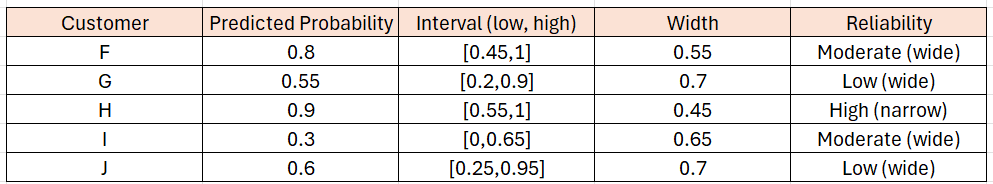 Table 2: Illustrative example for calculating the prediction intervals using conformal quantile
In this example, customer F has a high predicted probability of purchase (80%) but a moderately wide prediction interval, making it a less reliable prediction compared to customer H, who has both a high predicted probability (90%) and a narrow prediction interval.
Note that intervals are clipped to 0 and 1, since this is a binary classification model and probabilities cannot fall outside that range.
After applying the conformal quantile to the test set, it is useful to plot each test set data point to examine whether the prediction interval varies across observations.
 Figure 3: Plot showing the predicted probabilities (blue) and the prediction intervals (grey band) with a fixed interval approach
The fixed interval approach applies the same conformal quantile uniformly across all predictions, producing a constant-width band around each predicted probability. While straightforward to implement, this approach does not account for the fact that prediction uncertainty may vary across observations — a limitation that adaptive interval methods address by allowing interval width to scale with local model confidence.