Monitoring Embedding Drift in Production Scikit-LLM Pipelines
Learn what embedding drift is, why it matters for production LLMs, and how to implement two practical detection techniques using scikit-learn and Scikit-LLM.
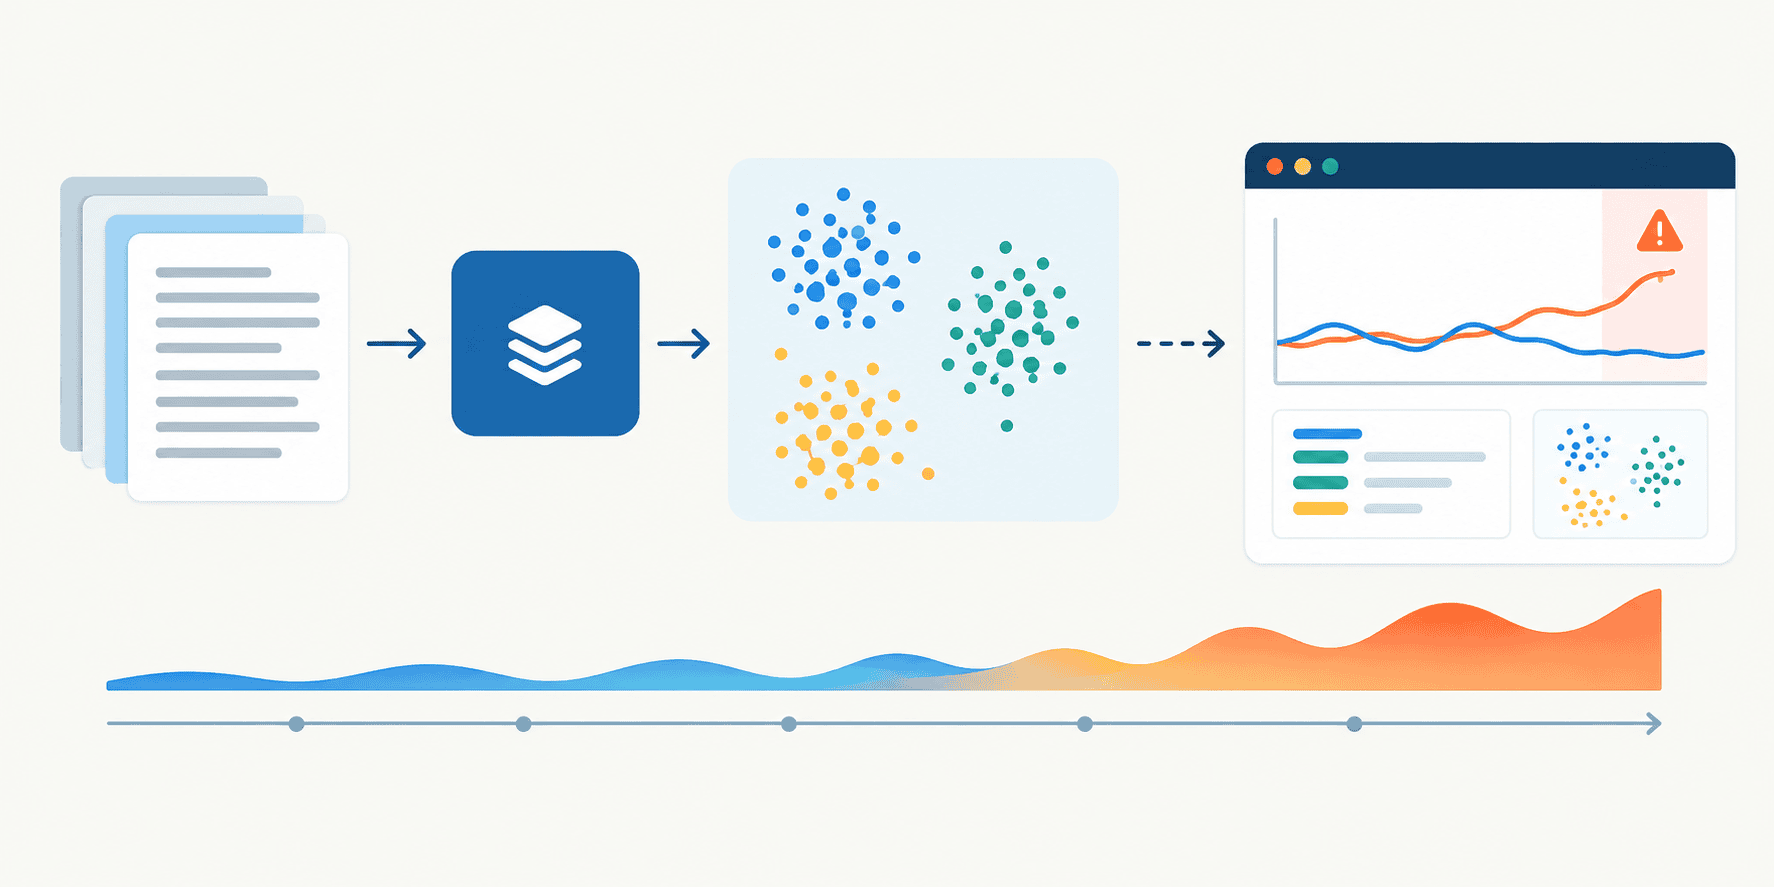
In this article, you will learn what embedding drift is, why it matters for production large language models, and how to implement two practical techniques to detect it.
Topics we will cover include:
- The key approaches for detecting embedding drift in production machine learning systems, including model-based detection, centroid distance, and dimensionality reduction combined with statistical tests.
- How to implement a domain classifier and a centroid distance method using scikit-learn on simulated 384-dimensional embeddings.
- How to apply these same drift detection techniques to real text embeddings generated with a SentenceTransformer model via Scikit-LLM.
Introduction
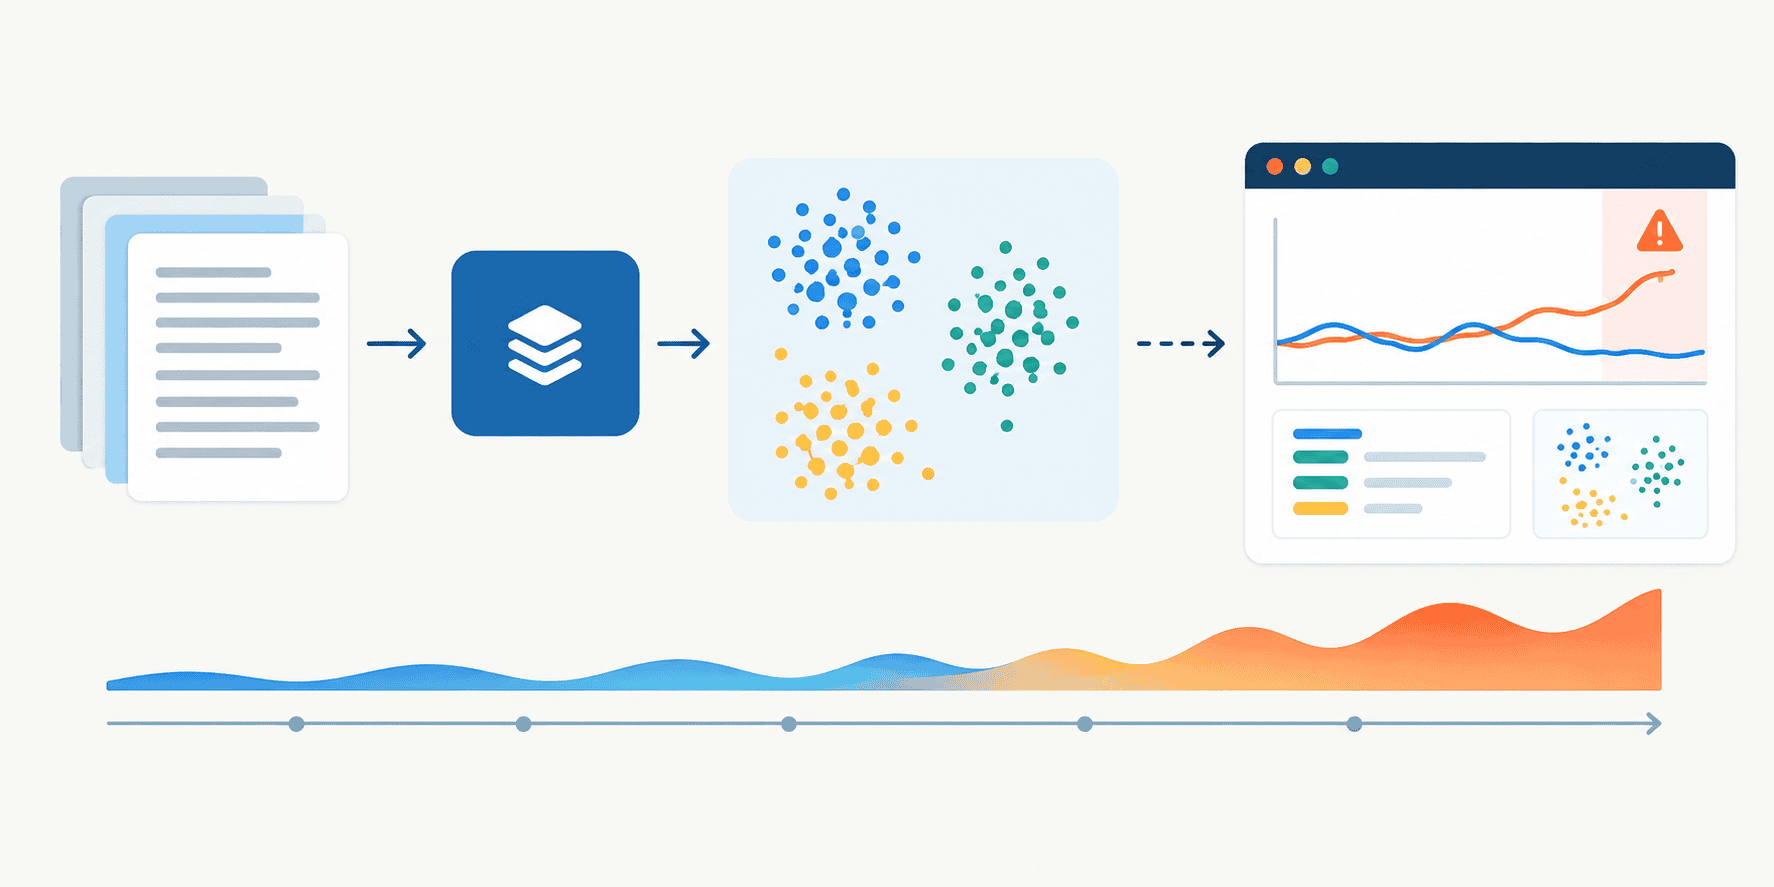
When a large language model (LLM) hits production, the story is far from over. User behavior inevitably evolves in the real world, and so does the data consumed by the model, typically encoded into numerical text representations called embeddings for its internal processing.
Therefore, it is crucial to track so-called embedding drifts to ascertain when a deployed model needs an update. However, traditional drift detection metrics designed for tabular data often fail when applied to high-dimensional embeddings.
This article starts by providing a brief outline of top techniques for detecting embedding drift, followed by an illustrative implementation of two of them, both simulation-based and in conjunction with the Scikit-LLM library for embedding generation.
Techniques for Effective Embedding Drift Detection
Below are three key approaches for accurately identifying embedding drift that have been put into practice in production LLMs:
- Model-based detection: This consists of training a domain-specific classifier, usually a binary classifier that has learned to distinguish between baseline data and new (drifted) production data. A model capable of easily telling them apart will be able to signal drifts when they occur.
- Centroid distance: Following classical anomaly detection algorithms, this strategy boils down to calculating the distance (often cosine for embedding data) between the center of mass of your baseline embedding vectors and that of new, incoming embedding vectors.
- Combining dimensionality reduction and statistical tests: This method entails compressing the embeddings to a lower dimension using UMAP or PCA, after which standard drift tests such as Kolmogorov-Smirnov are applied.
Illustrating Drift Detection on Simulated Embeddings
Let’s build a mathematical foundation for two of the listed techniques using standard scikit-learn and simulated embeddings. We generate an initial, random set of embeddings, after which we create another synthetic set — this time containing “production embeddings” that shift from the original embeddings’ mean to simulate the existence of data drift.
import numpy as np

# Simulating 384-dimensional embeddings (e.g. standard sentence-transformers output)
n_samples = 500
n_features = 384

# 1. Referencing Embeddings (Baseline / Training Data)
# Imagine this is the data your LLM/Vector DB was originally populated with
np.random.seed(42)
X_reference = np.random.normal(loc=0.0, scale=1.0, size=(n_samples, n_features))

# 2. Production Embeddings (New Data)
# The original mean is shifted to loc=0.3 to simulate data drift (e.g. new topic emerging)
X_production = np.random.normal(loc=0.3, scale=1.0, size=(n_samples, n_features))
Next, we train a domain classifier based on random forests to separate baseline data (labeled 0) from new, production data (labeled 1). If the accuracy metric — for instance, ROC-AUC — signals a high value, e.g. above 0.65, the classifier will trigger a drift alert.
from sklearn.ensemble import RandomForestClassifier
from sklearn.model_selection import train_test_split
from sklearn.metrics import roc_auc_score

# 1. Assigning labels: 0 for reference, baseline embeddings; 1 for production embeddings
y_reference = np.zeros(n_samples)
y_production = np.ones(n_samples)

# 2. Combining into a single dataset
X_combined = np.vstack((X_reference, X_production))
y_combined = np.hstack((y_reference, y_production))

# 3. Randomly splitting into train and test sets for the drift detector
X_train, X_test, y_train, y_test = train_test_split(
    X_combined, y_combined, test_size=0.3, random_state=42
)

# 4. Training a lightweight Random Forest classifier
drift_classifier = RandomForestClassifier(n_estimators=50, max_depth=5, random_state=42)
drift_classifier.fit(X_train, y_train)

# 5. Evaluating the classifier using ROC-AUC
y_pred_proba = drift_classifier.predict_proba(X_test)[:, 1]
roc_auc = roc_auc_score(y_test, y_pred_proba)
print(f"Domain Classifier ROC-AUC Score: {roc_auc:.3f}")

# 6. Alerting Logic
# If the metric score is around 0.5 it means the model can't tell the datasets apart (no drift detected).
# Meanwhile, a score closer to 1.0 means they are easily distinguishable (high drift).
if roc_auc > 0.65:
    print("ALERT: Significant embedding drift detected! Trigger retraining/review pipeline.")
else:
    print("System stable: Distributions are sufficiently similar.")
Output:
Domain Classifier ROC-AUC Score: 0.970
ALERT: Significant embedding drift detected! Trigger retraining/review pipeline.
Alternatively, we can resort to the centroid calculation technique, also known as the “center of mass” method, which measures the cosine distance between two centroids: one derived from the baseline embeddings and one from the new production embeddings. This method is computationally cheaper than the classifier approach, but it trades nuance for efficiency — aggregating high-dimensional vectors into a single central point can obscure localized drift that a domain classifier would otherwise catch. Despite this limitation, centroid distance remains a useful lightweight indicator for monitoring embedding shift in production pipelines.