High-Performance Data Processing with Polars: A Cheat Sheet
Polars is a Rust-based DataFrame library built for speed and efficiency. This cheat sheet covers its core functionality for high-performance data processing.
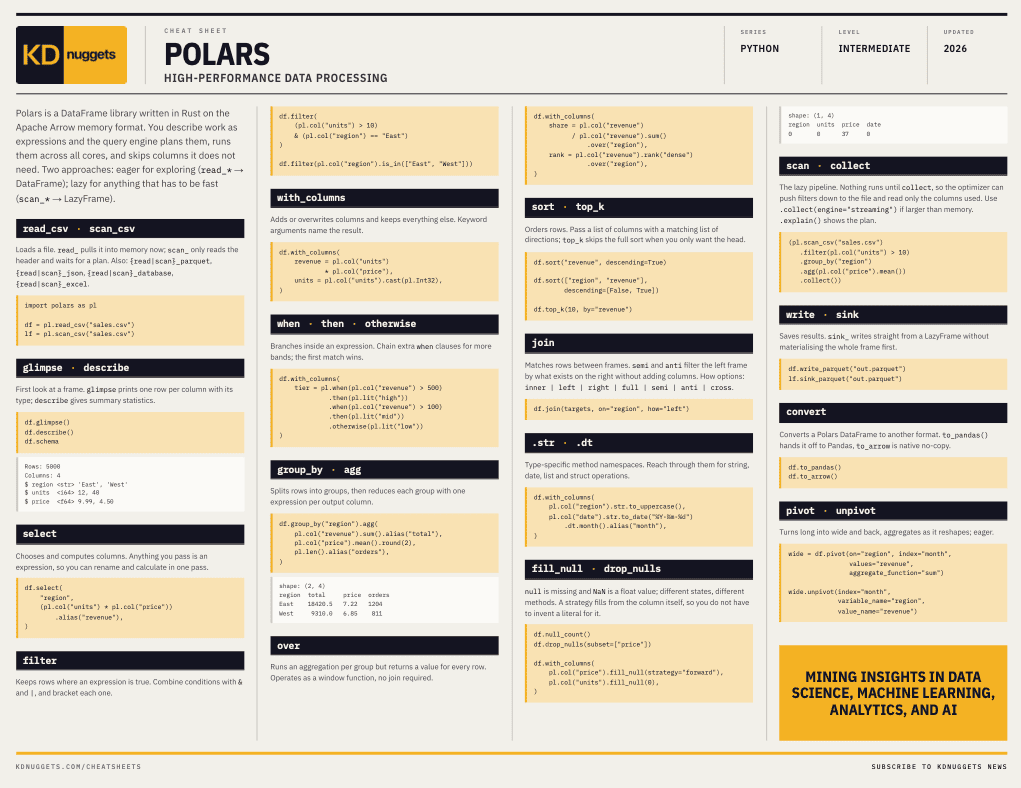
Most people arrive at Polars after a specific kind of frustration: they have a dataset that fits on disk but not in memory, or they try to perform a transformation that runs on one core while the other fifteen sit idle. Polars is a DataFrame library written in Rust on the Apache Arrow memory format, and the speed comes less from the language than from the model. The model? Describe your work as expressions, and the Polars query engine plans them out. It then decides how to execute them across all available cores, skipping unnecessary columns. The KDnuggets Polars cheat sheet gives you all of the foundational functionality needed to make Polars work best for you.
Lazy Evaluation with scan_csv and collect
That model is easiest to see in scan_csv and collect. Where read_csv pulls a file into memory immediately, scan_csv reads only the header and waits. Everything you chain after it is a description of intent; nothing executes until collect, which gives the optimizer room to push your filters down to the file itself and read only the columns your pipeline actually uses. For files larger than memory, collect(engine="streaming") processes in chunks rather than giving up.
Window Functions with over
The second big idea to know from the start is over. It runs an aggregation per group but returns a value for every row, meaning calculating each region’s share of its own total, or ranking within a category, requires no groupby-and-join treatment. It is a window function that reads like a normal column expression.
null vs. NaN: An Important Distinction
There is a small distinction that causes outsized confusion, so it’s worth addressing directly. In Polars, null means missing and NaN is an actual float value. They are different states with different methods, and expecting them to behave as one thing is a common early stumble.
What the Cheat Sheet Covers
Beyond those core concepts, the cheat sheet covers the full working surface:
- The core verb set of
select,filter, andwith_columns - Grouping and reshaping through
group_by,agg,pivot, andunpivot - Conditional logic with
when/then/otherwise - Joins, including the
semiandantivariants that filter without widening a frame - The
.strand.dtnamespaces for type-specific operations - Output options, where
sink_parquetwrites straight from a lazy frame without materializing it first - Interoperability via
to_pandasandto_arrow, because adopting Polars rarely means abandoning everything already built around pandas